source(here::here("common.R"))

# This notebook intentionally reads the RAW scores tibble (pre-cleaning)
# so the audit reflects the data as released. The cleaning decisions
# documented here are applied in 00_load_data, which produces the cleaned
# scores_all_sites.rds that 02 / 03 / tasks/ consume.
scores_all <- read_rds(here("data", "scores_raw.rds"))

audit_datasets <- c("pilot_mpieva_de_main", "pilot_uniandes_co_bogota")
scores <- scores_all |>
filter(dataset %in% audit_datasets, !is.na(score), !is.na(age))01 — Data integrity audit (Leipzig & Bogotá)
ImportantAI-generated — not for publication
The code and prose in this chapter were written by Claude Code (an AI coding agent) under human direction. They have not been line-by-line verified by a human and must not be published or cited as-is.
WarningPreliminary & unvetted analysis
These are exploratory analyses of preliminary, in-progress LEVANTE data. Results have not been reviewed or validated and require checking by the LEVANTE Data Coordinating Center before any use.
NoteNow on corrected data (v1.2)
Re-run on levante_data_latest v1.2 (IRT column-order scoring bug fixed). The large adaptive/non-adaptive mode shifts this audit originally flagged were mostly that bug: they have collapsed from ~+2.4 (Leipzig Math) and +1.1 (Vocab) to < 0.75 logits across the board. The “OK-mode” cautions below are therefore much less pressing. As of 2026-08 the Memory and Same-&-Different scoring concerns are also resolved (Memory: grid handled, switch-test passes — tasks/memory §4; SDS: corrected scoring landed in registry v2_3, final). The genuinely remaining issues are ROAR-Word non-engagement and a small residual EAP-shrinkage difference across the mode boundary.
Purpose
Before fitting growth models (02) or SEM (03), audit data integrity on the two longitudinal sites and produce a per-(site, task) verdict: usable as-is, usable with a filter, usable within one administration mode only, or drop.
Known issues from the LEVANTE data release notes:
- Adaptive vs non-adaptive ability scores aren’t fully comparable; CAT scores tend to be systematically lower because high-ability children ran out of time on non-adaptive variants and never saw harder items (ceiling-effect upward bias on non-adaptive).
- Non-adaptive variants were more common at earlier waves → confounds longitudinal change with administration-mode shift.
- Pattern Matching and Sentence Understanding show systematic T2 > T1 within both modes — could be training or developmental.
- Memory: known scoring bug, do not trust until next release.
- Same & Different: scoring will be updated next release.
- Surveys: still under development, use with caution.
Concerns originally flagged from the v1.0 spaghetti plots — math/vocab “depressed in adaptive”, shape-rotation decreases, Bogotá math “regression-to-mean compression”, pattern-matching downward trends — turned out to be overwhelmingly the column-order scoring bug (see reports/rlevante_handoff.html). On v1.2 they have collapsed (mode shifts now < 0.75 logits). What this audit now isolates are the genuinely remaining issues: ROAR-Word non-engagement and the unflagged adaptive rows (the Memory and Same-&-Different scoring flags were resolved in 2026-08 — see the verdict table).
Score scales by task
ROAR-Sentence and ROAR-Word are scored differently from the LEVANTE core tasks. ROAR-Word is a CAT theta (ability_cat), ROAR-Sentence is a guessing-adjusted raw count, ROAR-Phoneme is on the standard IRT theta scale. This affects how we should think about “extreme” scores.
scores |>
  count(dataset_label, task_label, score_type) |>
  pivot_wider(names_from = score_type, values_from = n, values_fill = 0L) |>
knitr::kable()| dataset_label | task_label | ability | guessing_adjusted_rate_scaled |
|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | 435 | 0 |
| Colombia — Bogotá | Math | 909 | 0 |
| Colombia — Bogotá | Memory | 344 | 0 |
| Colombia — Bogotá | Pattern Matching | 328 | 0 |
| Colombia — Bogotá | ROAR-Phoneme | 579 | 0 |
| Colombia — Bogotá | ROAR-Sentence | 0 | 770 |
| Colombia — Bogotá | ROAR-Word | 806 | 0 |
| Colombia — Bogotá | Same and Different | 204 | 0 |
| Colombia — Bogotá | Sentence Understanding | 454 | 0 |
| Colombia — Bogotá | Shape Rotation | 412 | 0 |
| Colombia — Bogotá | Stories (ToM) | 190 | 0 |
| Colombia — Bogotá | Vocabulary | 336 | 0 |
| Germany — Leipzig | Hearts and Flowers | 565 | 0 |
| Germany — Leipzig | Math | 535 | 0 |
| Germany — Leipzig | Memory | 540 | 0 |
| Germany — Leipzig | Pattern Matching | 507 | 0 |
| Germany — Leipzig | ROAR-Sentence | 0 | 201 |
| Germany — Leipzig | ROAR-Word | 207 | 0 |
| Germany — Leipzig | Same and Different | 543 | 0 |
| Germany — Leipzig | Sentence Understanding | 442 | 0 |
| Germany — Leipzig | Shape Rotation | 475 | 0 |
| Germany — Leipzig | Stories (ToM) | 528 | 0 |
| Germany — Leipzig | Vocabulary | 528 | 0 |
1. Coverage: adaptive × wave per (dataset, task)
For each (dataset, task), count runs by (wave, adaptive). This shows which cells are vulnerable to the CAT-vs-non-CAT confound.
waved <- scores |>
  group_by(dataset, user_id, task_id) |>
  arrange(age) |>
  mutate(wave = row_number()) |>
  ungroup() |>
  filter(wave <= 2)
cov_tbl <- waved |>
mutate(adaptive_lbl = case_when(
adaptive == TRUE ~ "adaptive",
adaptive == FALSE ~ "non-adapt",
TRUE ~ "unknown"
)) |>
count(dataset_label, task_label, task_category, wave, adaptive_lbl,
name = "n_runs")
ggplot(cov_tbl,
aes(x = factor(wave), y = n_runs, fill = adaptive_lbl)) +
geom_col(position = "stack") +
facet_grid(dataset_label ~ task_category + task_label,
scales = "free_x", space = "free_x") +
scale_fill_manual(values = c(adaptive = "#d33682",
`non-adapt` = "#268bd2",
unknown = "grey70")) +
labs(x = "Wave", y = "Runs", fill = NULL,
title = "Run counts by wave × adaptive (longitudinal datasets)") +
theme(strip.text.x = element_text(angle = 0, size = 8),
legend.position = "bottom",
panel.spacing.x = unit(0.05, "lines"))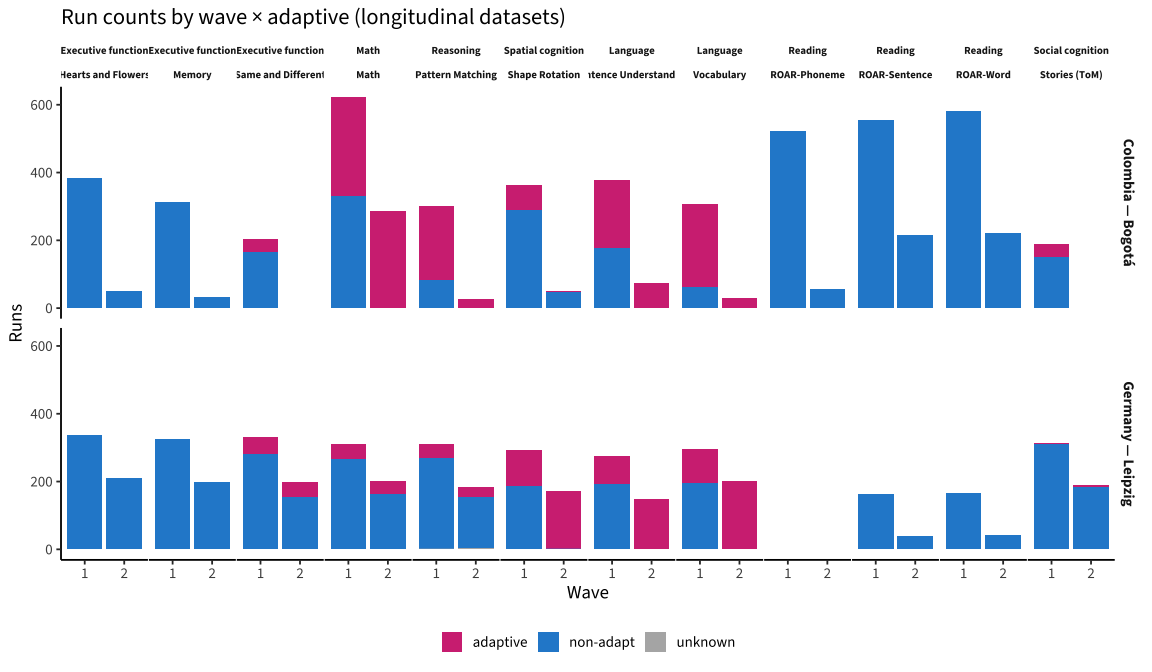
cov_tbl |>
  unite("cell", wave, adaptive_lbl, sep = "_") |>
  pivot_wider(names_from = cell, values_from = n_runs, values_fill = 0L) |>
  arrange(dataset_label, task_category, task_label) |>
  select(dataset_label, task_category, task_label,
         any_of(c("1_non-adapt","1_adaptive","1_unknown",
                  "2_non-adapt","2_adaptive","2_unknown"))) |>
knitr::kable()| dataset_label | task_category | task_label | 1_non-adapt | 1_adaptive | 1_unknown | 2_non-adapt | 2_adaptive | 2_unknown |
|---|---|---|---|---|---|---|---|---|
| Colombia — Bogotá | Executive function | Hearts and Flowers | 383 | 0 | 0 | 52 | 0 | 0 |
| Colombia — Bogotá | Executive function | Memory | 312 | 0 | 0 | 32 | 0 | 0 |
| Colombia — Bogotá | Executive function | Same and Different | 166 | 38 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | Math | Math | 332 | 290 | 0 | 0 | 287 | 0 |
| Colombia — Bogotá | Reasoning | Pattern Matching | 82 | 219 | 0 | 0 | 27 | 0 |
| Colombia — Bogotá | Spatial cognition | Shape Rotation | 290 | 72 | 0 | 49 | 1 | 0 |
| Colombia — Bogotá | Language | Sentence Understanding | 177 | 202 | 0 | 0 | 75 | 0 |
| Colombia — Bogotá | Language | Vocabulary | 63 | 244 | 0 | 0 | 29 | 0 |
| Colombia — Bogotá | Reading | ROAR-Phoneme | 522 | 0 | 0 | 57 | 0 | 0 |
| Colombia — Bogotá | Reading | ROAR-Sentence | 554 | 0 | 0 | 215 | 0 | 0 |
| Colombia — Bogotá | Reading | ROAR-Word | 583 | 0 | 0 | 223 | 0 | 0 |
| Colombia — Bogotá | Social cognition | Stories (ToM) | 151 | 39 | 0 | 0 | 0 | 0 |
| Germany — Leipzig | Executive function | Hearts and Flowers | 337 | 0 | 0 | 210 | 0 | 0 |
| Germany — Leipzig | Executive function | Memory | 325 | 0 | 0 | 198 | 0 | 0 |
| Germany — Leipzig | Executive function | Same and Different | 281 | 50 | 0 | 153 | 46 | 0 |
| Germany — Leipzig | Math | Math | 266 | 44 | 0 | 164 | 39 | 0 |
| Germany — Leipzig | Reasoning | Pattern Matching | 267 | 42 | 1 | 149 | 30 | 5 |
| Germany — Leipzig | Spatial cognition | Shape Rotation | 188 | 104 | 0 | 1 | 170 | 0 |
| Germany — Leipzig | Language | Sentence Understanding | 192 | 84 | 0 | 0 | 148 | 0 |
| Germany — Leipzig | Language | Vocabulary | 196 | 100 | 0 | 0 | 203 | 0 |
| Germany — Leipzig | Reading | ROAR-Sentence | 162 | 0 | 0 | 38 | 0 | 0 |
| Germany — Leipzig | Reading | ROAR-Word | 165 | 0 | 0 | 41 | 0 | 0 |
| Germany — Leipzig | Social cognition | Stories (ToM) | 312 | 2 | 0 | 183 | 8 | 0 |
2. Score distributions by adaptive
Histograms of all scored runs (T1+T2 pooled) split by adaptive flag. If CAT and non-CAT are on the same scale, the distributions should overlap. Where they don’t, that’s the artifact.
waved |>
  filter(!is.na(adaptive)) |>
  ggplot(aes(x = score, fill = adaptive)) +
  geom_histogram(bins = 40, alpha = 0.7, position = "identity") +
  facet_grid(dataset_label ~ task_category + task_label,
             scales = "free", space = "free_x") +
  scale_fill_manual(values = c(`FALSE` = "#268bd2", `TRUE` = "#d33682"),
                    labels = c("non-adaptive", "adaptive"),
                    name = NULL) +
  labs(x = "Score", y = "Count",
       title = "Score distributions by adaptive flag") +
  theme(strip.text.x = element_text(angle = 0, size = 7),
        legend.position = "bottom",
        panel.spacing.x = unit(0.05, "lines"))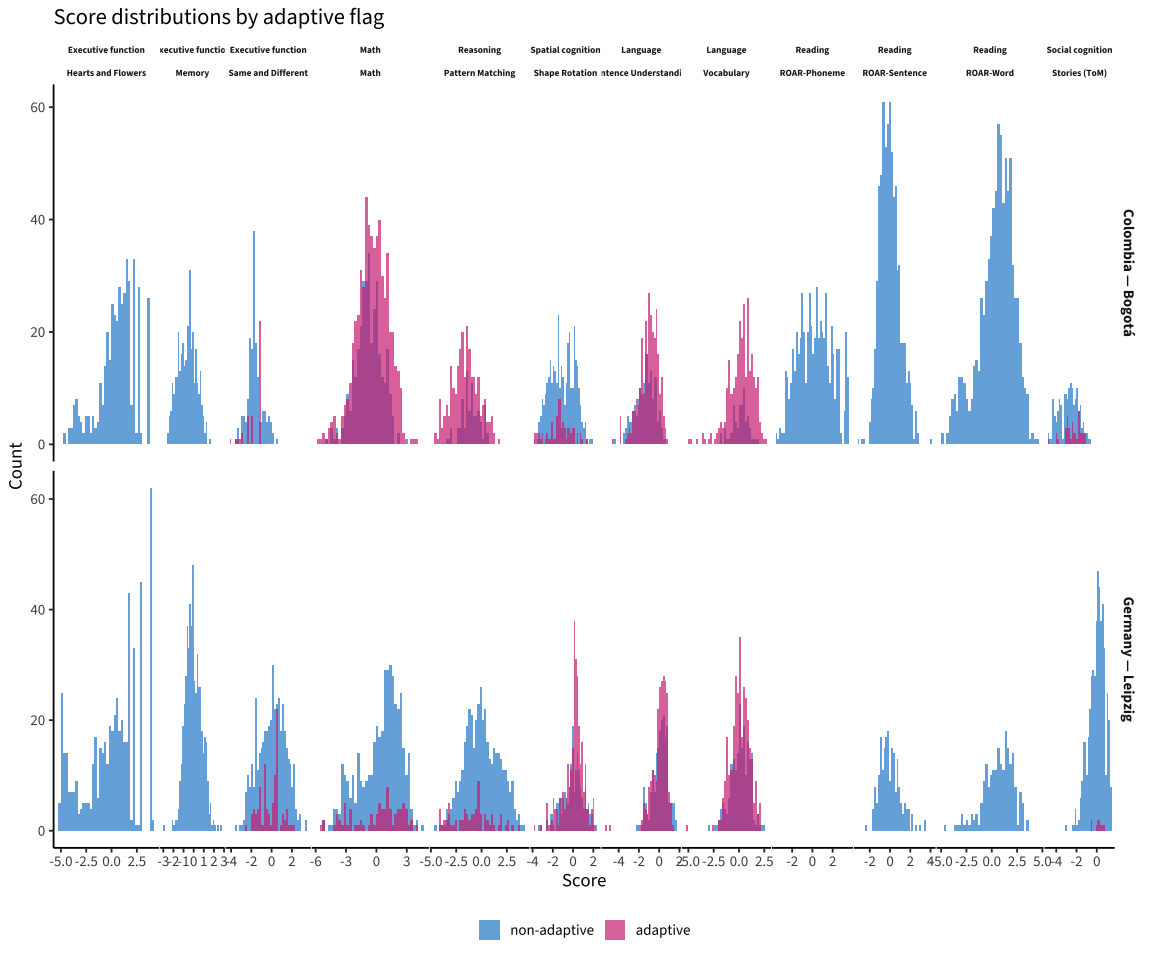
waved |>
  filter(!is.na(adaptive)) |>
  group_by(dataset_label, task_label, adaptive) |>
  summarise(n = n(),
            mean = mean(score, na.rm = TRUE),
            sd   = sd(score, na.rm = TRUE),
            p10  = quantile(score, 0.1, na.rm = TRUE),
            p90  = quantile(score, 0.9, na.rm = TRUE),
            .groups = "drop") |>
  pivot_wider(names_from = adaptive,
              values_from = c(n, mean, sd, p10, p90)) |>
  mutate(mean_shift_NA_minus_A = mean_FALSE - mean_TRUE) |>
  arrange(dataset_label, task_label) |>
knitr::kable(digits = 2)| dataset_label | task_label | n_FALSE | n_TRUE | mean_FALSE | mean_TRUE | sd_FALSE | sd_TRUE | p10_FALSE | p10_TRUE | p90_FALSE | p90_TRUE | mean_shift_NA_minus_A |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | 435 | NA | 0.61 | NA | 1.81 | NA | -2.18 | NA | 2.75 | NA | NA |
| Colombia — Bogotá | Math | 332 | 577 | -0.77 | -0.41 | 1.29 | 1.57 | -2.38 | -2.33 | 0.99 | 1.55 | -0.36 |
| Colombia — Bogotá | Memory | 344 | NA | -0.63 | NA | 0.89 | NA | -1.86 | NA | 0.55 | NA | NA |
| Colombia — Bogotá | Pattern Matching | 82 | 246 | -1.09 | -1.60 | 0.91 | 1.31 | -2.06 | -3.35 | 0.30 | 0.22 | 0.51 |
| Colombia — Bogotá | ROAR-Phoneme | 579 | NA | 0.26 | NA | 1.67 | NA | -1.97 | NA | 2.54 | NA | NA |
| Colombia — Bogotá | ROAR-Sentence | 769 | NA | -0.05 | NA | 0.97 | NA | -1.15 | NA | 1.30 | NA | NA |
| Colombia — Bogotá | ROAR-Word | 806 | NA | 0.45 | NA | 1.74 | NA | -2.09 | NA | 2.46 | NA | NA |
| Colombia — Bogotá | Same and Different | 166 | 38 | -1.67 | -1.82 | 0.75 | 0.77 | -2.51 | -2.94 | -0.53 | -1.28 | 0.15 |
| Colombia — Bogotá | Sentence Understanding | 177 | 277 | -1.34 | -1.03 | 0.95 | 0.93 | -2.65 | -2.25 | -0.22 | 0.06 | -0.31 |
| Colombia — Bogotá | Shape Rotation | 339 | 73 | -1.05 | -1.34 | 1.20 | 1.19 | -2.67 | -3.20 | 0.45 | 0.13 | 0.29 |
| Colombia — Bogotá | Stories (ToM) | 151 | 39 | -2.77 | -2.38 | 0.93 | 0.86 | -4.12 | -3.23 | -1.60 | -1.40 | -0.39 |
| Colombia — Bogotá | Vocabulary | 63 | 273 | 0.12 | 0.19 | 0.77 | 1.23 | -0.82 | -1.16 | 0.96 | 1.63 | -0.07 |
| Germany — Leipzig | Hearts and Flowers | 547 | NA | 0.15 | NA | 2.65 | NA | -4.37 | NA | 3.90 | NA | NA |
| Germany — Leipzig | Math | 430 | 83 | 0.41 | 0.06 | 1.98 | 2.42 | -2.76 | -3.47 | 2.65 | 2.76 | 0.34 |
| Germany — Leipzig | Memory | 523 | NA | -0.04 | NA | 0.79 | NA | -0.98 | NA | 1.05 | NA | NA |
| Germany — Leipzig | Pattern Matching | 416 | 72 | 0.03 | -0.89 | 1.69 | 1.92 | -2.16 | -3.45 | 2.37 | 1.91 | 0.92 |
| Germany — Leipzig | ROAR-Sentence | 200 | NA | 0.00 | NA | 1.00 | NA | -1.14 | NA | 1.37 | NA | NA |
| Germany — Leipzig | ROAR-Word | 206 | NA | 0.65 | NA | 1.48 | NA | -1.06 | NA | 2.28 | NA | NA |
| Germany — Leipzig | Same and Different | 434 | 96 | 0.03 | -0.11 | 1.33 | 1.03 | -1.77 | -1.62 | 1.76 | 1.21 | 0.14 |
| Germany — Leipzig | Sentence Understanding | 192 | 232 | 0.11 | 0.05 | 0.78 | 0.81 | -0.99 | -0.94 | 1.01 | 0.80 | 0.06 |
| Germany — Leipzig | Shape Rotation | 189 | 274 | -0.03 | 0.08 | 1.13 | 0.94 | -1.64 | -1.18 | 1.46 | 1.12 | -0.11 |
| Germany — Leipzig | Stories (ToM) | 495 | 10 | 0.00 | 0.16 | 0.77 | 0.43 | -1.13 | -0.46 | 1.00 | 0.67 | -0.17 |
| Germany — Leipzig | Vocabulary | 196 | 303 | 0.11 | 0.09 | 0.92 | 0.92 | -1.08 | -1.11 | 1.21 | 1.21 | 0.02 |
3. Within-child change by adaptive transition
For each child with T1 and T2, classify the (T1 mode → T2 mode) transition, then compute the delta. A clean “developmental change” estimate requires the mode to stay the same across waves.
pairs <- waved |>
  group_by(dataset, dataset_label, user_id, task_id, task_label, task_category) |>
  filter(n_distinct(wave) == 2) |>
  summarise(
    score_t1 = score[wave == 1],
    score_t2 = score[wave == 2],
    age_t1   = age[wave == 1],
    age_t2   = age[wave == 2],
    adapt_t1 = adaptive[wave == 1],
    adapt_t2 = adaptive[wave == 2],
    .groups  = "drop"
  ) |>
  mutate(
    delta   = score_t2 - score_t1,
    age_gap = (age_t2 - age_t1) * 12,
    transition = case_when(
      is.na(adapt_t1) | is.na(adapt_t2) ~ "unknown",
      adapt_t1 == FALSE & adapt_t2 == FALSE ~ "NA→NA",
      adapt_t1 == FALSE & adapt_t2 == TRUE  ~ "NA→A",
      adapt_t1 == TRUE  & adapt_t2 == TRUE  ~ "A→A",
      adapt_t1 == TRUE  & adapt_t2 == FALSE ~ "A→NA"
    )
  )

pairs |>
  count(dataset_label, task_label, transition) |>
  pivot_wider(names_from = transition, values_from = n, values_fill = 0L) |>
  arrange(dataset_label, task_label) |>
knitr::kable()| dataset_label | task_label | NA→NA | A→A | NA→A | unknown | A→NA |
|---|---|---|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | 52 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | Math | 0 | 53 | 234 | 0 | 0 |
| Colombia — Bogotá | Memory | 32 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | Pattern Matching | 0 | 0 | 27 | 0 | 0 |
| Colombia — Bogotá | ROAR-Phoneme | 57 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | ROAR-Sentence | 215 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | ROAR-Word | 223 | 0 | 0 | 0 | 0 |
| Colombia — Bogotá | Sentence Understanding | 0 | 0 | 75 | 0 | 0 |
| Colombia — Bogotá | Shape Rotation | 49 | 1 | 0 | 0 | 0 |
| Colombia — Bogotá | Vocabulary | 0 | 0 | 29 | 0 | 0 |
| Germany — Leipzig | Hearts and Flowers | 210 | 0 | 0 | 0 | 0 |
| Germany — Leipzig | Math | 164 | 36 | 3 | 0 | 0 |
| Germany — Leipzig | Memory | 198 | 0 | 0 | 0 | 0 |
| Germany — Leipzig | Pattern Matching | 149 | 30 | 0 | 5 | 0 |
| Germany — Leipzig | ROAR-Sentence | 38 | 0 | 0 | 0 | 0 |
| Germany — Leipzig | ROAR-Word | 41 | 0 | 0 | 0 | 0 |
| Germany — Leipzig | Same and Different | 153 | 38 | 8 | 0 | 0 |
| Germany — Leipzig | Sentence Understanding | 0 | 39 | 109 | 0 | 0 |
| Germany — Leipzig | Shape Rotation | 0 | 42 | 128 | 0 | 1 |
| Germany — Leipzig | Stories (ToM) | 183 | 0 | 8 | 0 | 0 |
| Germany — Leipzig | Vocabulary | 0 | 39 | 164 | 0 | 0 |
pairs |>
  filter(transition %in% c("NA→NA", "NA→A", "A→A")) |>
  group_by(dataset_label, task_label, transition) |>
  filter(n() >= 10) |>
  summarise(n = n(),
            mean_delta = mean(delta, na.rm = TRUE),
            sd_delta   = sd(delta, na.rm = TRUE),
            median_age_gap_m = median(age_gap, na.rm = TRUE),
            .groups = "drop") |>
  arrange(dataset_label, task_label, transition) |>
knitr::kable(digits = 2)| dataset_label | task_label | transition | n | mean_delta | sd_delta | median_age_gap_m |
|---|---|---|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | NA→NA | 52 | 0.83 | 1.99 | 15.6 |
| Colombia — Bogotá | Math | A→A | 53 | 0.76 | 0.93 | 9.6 |
| Colombia — Bogotá | Math | NA→A | 234 | 0.85 | 0.95 | 15.6 |
| Colombia — Bogotá | Memory | NA→NA | 32 | 0.46 | 0.94 | 15.6 |
| Colombia — Bogotá | Pattern Matching | NA→A | 27 | -0.26 | 1.25 | 15.6 |
| Colombia — Bogotá | ROAR-Phoneme | NA→NA | 57 | -0.04 | 1.62 | 9.6 |
| Colombia — Bogotá | ROAR-Sentence | NA→NA | 215 | 0.49 | 0.73 | 15.6 |
| Colombia — Bogotá | ROAR-Word | NA→NA | 223 | 0.58 | 1.61 | 15.6 |
| Colombia — Bogotá | Sentence Understanding | NA→A | 75 | 0.66 | 0.86 | 15.6 |
| Colombia — Bogotá | Shape Rotation | NA→NA | 49 | 0.76 | 0.91 | 15.6 |
| Colombia — Bogotá | Vocabulary | NA→A | 29 | 0.30 | 1.04 | 15.6 |
| Germany — Leipzig | Hearts and Flowers | NA→NA | 210 | 0.49 | 2.51 | 3.6 |
| Germany — Leipzig | Math | A→A | 36 | 0.00 | 1.23 | 2.4 |
| Germany — Leipzig | Math | NA→NA | 164 | 0.01 | 1.11 | 3.6 |
| Germany — Leipzig | Memory | NA→NA | 198 | 0.24 | 0.70 | 3.6 |
| Germany — Leipzig | Pattern Matching | A→A | 30 | 0.18 | 1.67 | 2.4 |
| Germany — Leipzig | Pattern Matching | NA→NA | 149 | -0.33 | 1.43 | 3.6 |
| Germany — Leipzig | ROAR-Sentence | NA→NA | 38 | 0.42 | 0.69 | 3.6 |
| Germany — Leipzig | ROAR-Word | NA→NA | 41 | 0.00 | 1.12 | 4.8 |
| Germany — Leipzig | Same and Different | A→A | 38 | 0.14 | 1.17 | 3.0 |
| Germany — Leipzig | Same and Different | NA→NA | 153 | 0.26 | 1.32 | 3.6 |
| Germany — Leipzig | Sentence Understanding | A→A | 39 | 0.24 | 0.60 | 2.4 |
| Germany — Leipzig | Sentence Understanding | NA→A | 109 | -0.09 | 0.80 | 4.8 |
| Germany — Leipzig | Shape Rotation | A→A | 42 | 0.17 | 1.12 | 2.4 |
| Germany — Leipzig | Shape Rotation | NA→A | 128 | 0.21 | 0.84 | 3.6 |
| Germany — Leipzig | Stories (ToM) | NA→NA | 183 | -0.14 | 0.76 | 3.6 |
| Germany — Leipzig | Vocabulary | A→A | 39 | 0.02 | 1.07 | 2.4 |
| Germany — Leipzig | Vocabulary | NA→A | 164 | 0.10 | 0.65 | 3.6 |
pairs |>
  filter(transition %in% c("NA→NA", "NA→A", "A→A")) |>
  group_by(dataset_label, task_label, transition) |>
  filter(n() >= 10) |>
  ungroup() |>
  ggplot(aes(x = delta, fill = transition)) +
  geom_histogram(bins = 30, alpha = 0.7, position = "identity") +
  geom_vline(xintercept = 0, lty = 3) +
  facet_grid(dataset_label ~ task_category + task_label,
             scales = "free", space = "free_x") +
  scale_fill_brewer(palette = "Set2") +
  labs(x = "Score T2 − T1", y = "Children",
       title = "Within-child change by adaptive transition",
       fill = NULL) +
  theme(strip.text.x = element_text(angle = 0, size = 7),
        legend.position = "bottom",
        panel.spacing.x = unit(0.05, "lines"))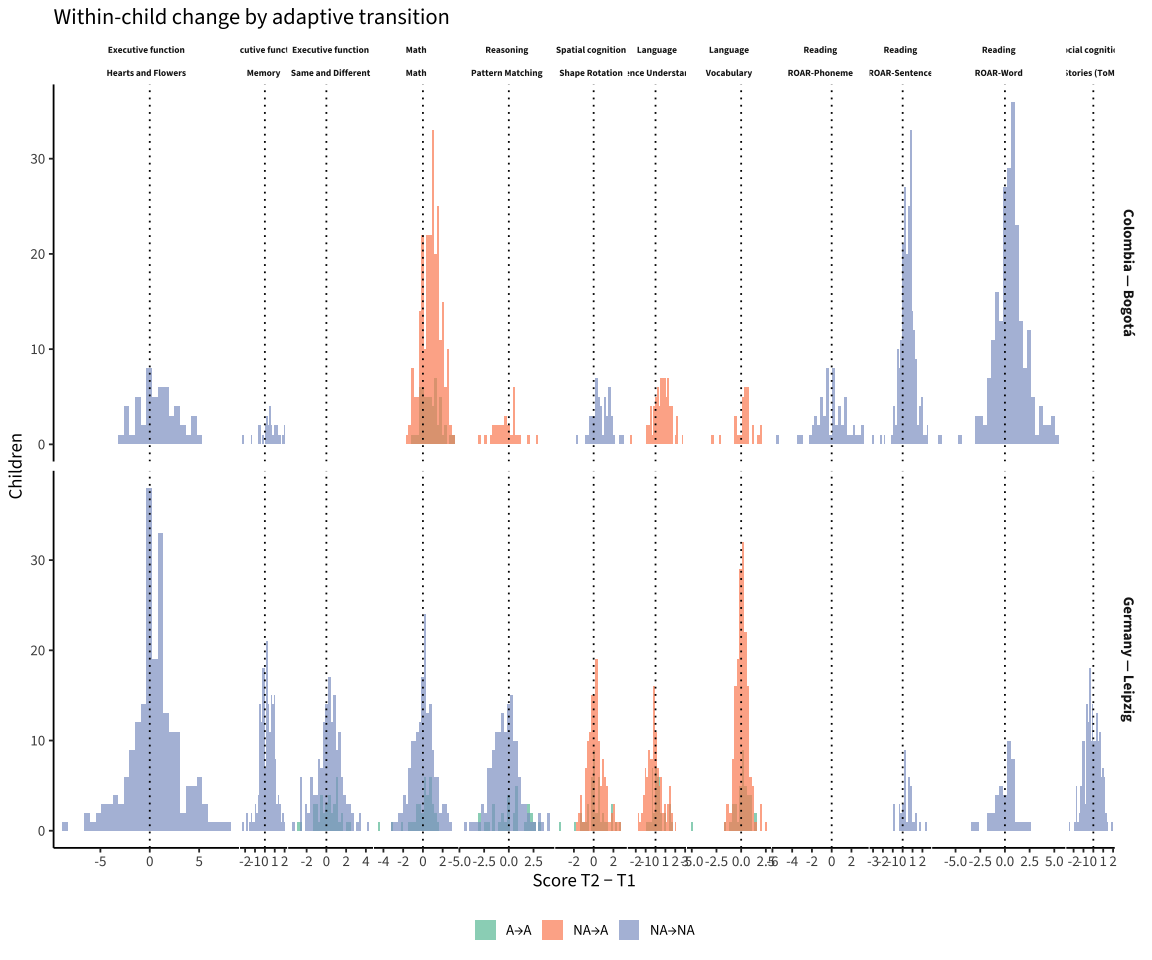
4. Regression-to-mean (Galton’s regression)
For each (dataset, task) with ≥ 30 two-wave kids, fit score_t2 ~ score_t1 restricted to mode-stable transitions. A slope of 1 means no regression to mean (perfect persistence; differences reflect actual growth). A slope < 1 means high T1 scorers regress down and low T1 scorers regress up. The shift from slope-1 is approximately 1 - reliability + change_dependence.
rtm <- pairs |>
  filter(transition %in% c("NA→NA", "A→A")) |>
  group_by(dataset_label, task_label, transition) |>
  filter(n() >= 30) |>
  summarise(
    n = n(),
    galton_slope     = coef(lm(score_t2 ~ score_t1))[2],
    galton_se        = summary(lm(score_t2 ~ score_t1))$coefficients[2, 2],
    intercept_shift  = coef(lm(score_t2 ~ score_t1))[1],
    cor_t1_t2        = cor(score_t1, score_t2),
    .groups = "drop"
  )

knitr::kable(rtm, digits = 3)| dataset_label | task_label | transition | n | galton_slope | galton_se | intercept_shift | cor_t1_t2 |
|---|---|---|---|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | NA→NA | 52 | 0.348 | 0.084 | 0.870 | 0.507 |
| Colombia — Bogotá | Math | A→A | 53 | 0.752 | 0.072 | 0.428 | 0.826 |
| Colombia — Bogotá | Memory | NA→NA | 32 | 0.314 | 0.224 | -0.094 | 0.248 |
| Colombia — Bogotá | ROAR-Phoneme | NA→NA | 57 | 0.522 | 0.127 | -0.278 | 0.486 |
| Colombia — Bogotá | ROAR-Sentence | NA→NA | 215 | 0.832 | 0.060 | 0.443 | 0.691 |
| Colombia — Bogotá | ROAR-Word | NA→NA | 223 | 0.522 | 0.050 | 0.684 | 0.577 |
| Colombia — Bogotá | Shape Rotation | NA→NA | 49 | 0.809 | 0.137 | 0.422 | 0.653 |
| Germany — Leipzig | Hearts and Flowers | NA→NA | 210 | 0.502 | 0.055 | 0.428 | 0.536 |
| Germany — Leipzig | Math | A→A | 36 | 0.857 | 0.084 | 0.027 | 0.869 |
| Germany — Leipzig | Math | NA→NA | 164 | 0.733 | 0.035 | 0.101 | 0.855 |
| Germany — Leipzig | Memory | NA→NA | 198 | 0.689 | 0.066 | 0.183 | 0.596 |
| Germany — Leipzig | Pattern Matching | A→A | 30 | 0.593 | 0.159 | -0.300 | 0.576 |
| Germany — Leipzig | Pattern Matching | NA→NA | 149 | 0.596 | 0.058 | -0.253 | 0.644 |
| Germany — Leipzig | ROAR-Sentence | NA→NA | 38 | 1.127 | 0.119 | 0.436 | 0.845 |
| Germany — Leipzig | ROAR-Word | NA→NA | 41 | 0.809 | 0.139 | 0.163 | 0.682 |
| Germany — Leipzig | Same and Different | A→A | 38 | 0.470 | 0.173 | 0.026 | 0.412 |
| Germany — Leipzig | Same and Different | NA→NA | 153 | 0.615 | 0.080 | 0.267 | 0.530 |
| Germany — Leipzig | Sentence Understanding | A→A | 39 | 0.847 | 0.086 | 0.181 | 0.850 |
| Germany — Leipzig | Shape Rotation | A→A | 42 | 0.371 | 0.159 | 0.008 | 0.347 |
| Germany — Leipzig | Stories (ToM) | NA→NA | 183 | 0.485 | 0.058 | -0.108 | 0.526 |
| Germany — Leipzig | Vocabulary | A→A | 39 | 0.489 | 0.232 | -0.110 | 0.327 |
pairs |>
  filter(transition %in% c("NA→NA", "A→A")) |>
  group_by(dataset_label, task_label, transition) |>
  filter(n() >= 30) |>
  ungroup() |>
  ggplot(aes(x = score_t1, y = score_t2, color = transition)) +
  geom_abline(slope = 1, intercept = 0, lty = 3, color = "grey50") +
  geom_point(alpha = 0.35, size = 0.8) +
  geom_smooth(method = "lm", se = FALSE) +
  facet_grid(dataset_label ~ task_category + task_label, scales = "free") +
  scale_color_brewer(palette = "Set2") +
  labs(x = "Score T1", y = "Score T2",
       title = "Galton's regression: T2 on T1 (mode-stable transitions)",
       subtitle = "Dotted = identity; coloured line = OLS fit",
       color = NULL) +
  theme(strip.text.x = element_text(angle = 0, size = 7),
        legend.position = "bottom",
        panel.spacing.x = unit(0.05, "lines"))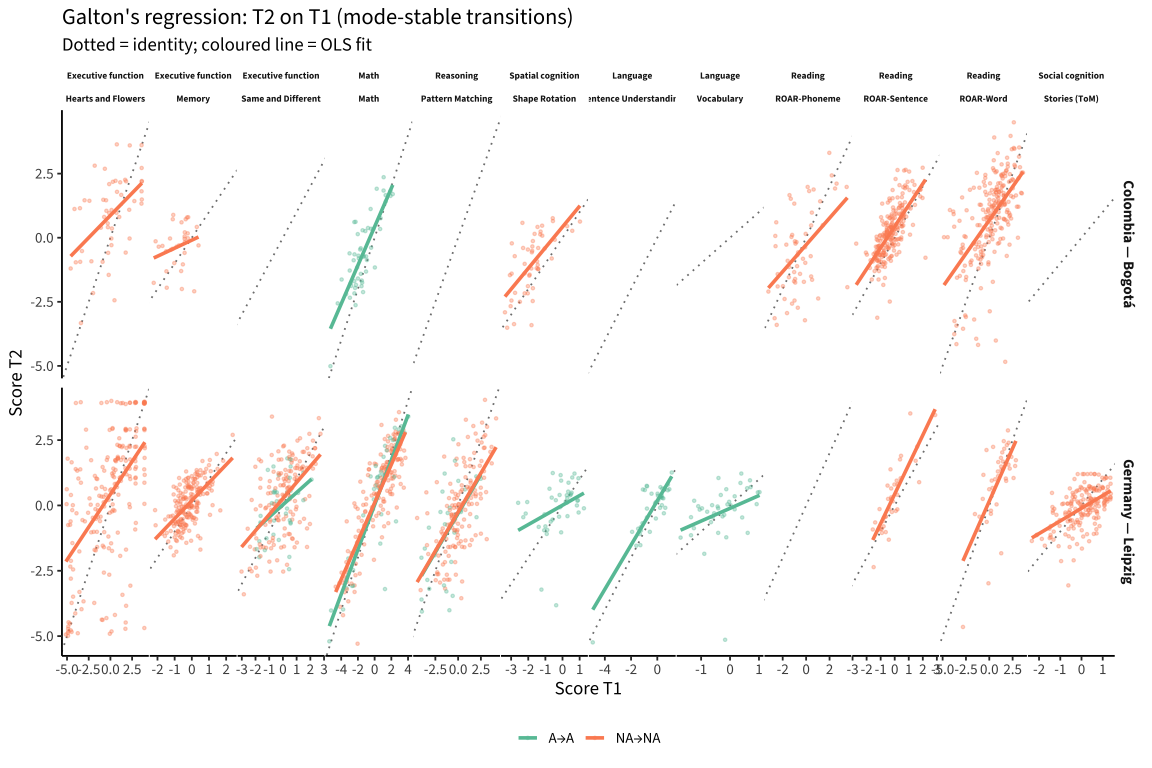
5. Extreme low / high scores
Flag runs with |score| > 4 on the IRT theta scale. For ROAR-Word (ability_cat) and ROAR-Phoneme this is the same θ scale; for ROAR-Sentence the scale is “guessing-adjusted raw” so a separate threshold (|x| > 4 SDs of that task) applies.
extreme <- waved |>
  group_by(dataset, task_id, task_label, score_type) |>
  mutate(z = if_else(score_type == "guessing_adjusted_number_correct_scaled",
                     (score - mean(score, na.rm = TRUE)) /
                       sd(score, na.rm = TRUE),
                     score)) |>
  ungroup() |>
  filter(abs(z) > 4)

extreme |>
  count(dataset_label, task_label, name = "n_extreme") |>
  arrange(desc(n_extreme)) |>
knitr::kable()| dataset_label | task_label | n_extreme |
|---|---|---|
| Germany — Leipzig | Hearts and Flowers | 67 |
| Colombia — Bogotá | Math | 23 |
| Colombia — Bogotá | Stories (ToM) | 21 |
| Germany — Leipzig | Math | 15 |
| Colombia — Bogotá | ROAR-Word | 12 |
| Colombia — Bogotá | Pattern Matching | 11 |
| Germany — Leipzig | Pattern Matching | 8 |
| Colombia — Bogotá | Hearts and Flowers | 6 |
| Colombia — Bogotá | Vocabulary | 3 |
| Colombia — Bogotá | Sentence Understanding | 2 |
| Germany — Leipzig | Sentence Understanding | 2 |
| Colombia — Bogotá | ROAR-Sentence | 1 |
| Colombia — Bogotá | Same and Different | 1 |
| Germany — Leipzig | ROAR-Word | 1 |
| Germany — Leipzig | Vocabulary | 1 |
extreme |>
  group_by(dataset_label, task_label) |>
  summarise(
    n         = n(),
    median_age = median(age),
    median_num_attempted = median(num_attempted, na.rm = TRUE),
    median_score_se = median(score_se, na.rm = TRUE),
    pct_adaptive = mean(adaptive, na.rm = TRUE) * 100,
    score_range = paste(round(min(score), 1), round(max(score), 1), sep = " to "),
    .groups = "drop"
  ) |>
  arrange(dataset_label, task_label) |>
knitr::kable(digits = 2)| dataset_label | task_label | n | median_age | median_num_attempted | median_score_se | pct_adaptive | score_range |
|---|---|---|---|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | 6 | 6.55 | 60.0 | 0.80 | 0.00 | -4.7 to -4.1 |
| Colombia — Bogotá | Math | 23 | 6.50 | 40.0 | 0.50 | 78.26 | -5.7 to 4.1 |
| Colombia — Bogotá | Pattern Matching | 11 | 7.60 | 35.0 | 0.83 | 100.00 | -4.6 to -4 |
| Colombia — Bogotá | ROAR-Sentence | 1 | 12.70 | 99.0 | NA | 0.00 | 4 to 4 |
| Colombia — Bogotá | ROAR-Word | 12 | 7.55 | 102.0 | 0.78 | 0.00 | -4.8 to 4.5 |
| Colombia — Bogotá | Same and Different | 1 | 6.50 | 9.0 | 0.52 | 100.00 | -4.1 to -4.1 |
| Colombia — Bogotá | Sentence Understanding | 2 | 6.20 | 48.0 | 0.57 | 50.00 | -4.6 to -4.4 |
| Colombia — Bogotá | Stories (ToM) | 21 | 6.90 | 15.0 | 0.73 | 14.29 | -4.8 to -4 |
| Colombia — Bogotá | Vocabulary | 3 | 9.30 | 161.0 | 0.56 | 100.00 | -4.8 to -4.1 |
| Germany — Leipzig | Hearts and Flowers | 67 | 6.90 | 60.0 | 0.77 | 0.00 | -5.1 to 4.1 |
| Germany — Leipzig | Math | 15 | 6.10 | 32.0 | 0.49 | 33.33 | -5.4 to 4.5 |
| Germany — Leipzig | Pattern Matching | 8 | 6.75 | 30.5 | 0.86 | 50.00 | -4.5 to 4.2 |
| Germany — Leipzig | ROAR-Word | 1 | 9.70 | 120.0 | 0.63 | 0.00 | -4.7 to -4.7 |
| Germany — Leipzig | Sentence Understanding | 2 | 9.60 | 37.5 | 0.41 | 100.00 | -5.2 to -4.9 |
| Germany — Leipzig | Vocabulary | 1 | 9.70 | 38.0 | 0.42 | 100.00 | -5.1 to -5.1 |
extreme |>
  ggplot(aes(x = num_attempted, y = score, color = adaptive)) +
  geom_point(alpha = 0.6) +
  facet_wrap(vars(dataset_label, task_label), scales = "free") +
  scale_color_manual(values = c(`FALSE` = "#268bd2", `TRUE` = "#d33682"),
                     labels = c("non-adapt", "adaptive"),
                     na.value = "grey60", name = NULL) +
  labs(x = "Number of items attempted", y = "Score",
       title = "Extreme scores vs. number of items attempted",
       subtitle = "If extreme scores cluster at low num_attempted, they're likely scoring noise") +
  theme(legend.position = "bottom")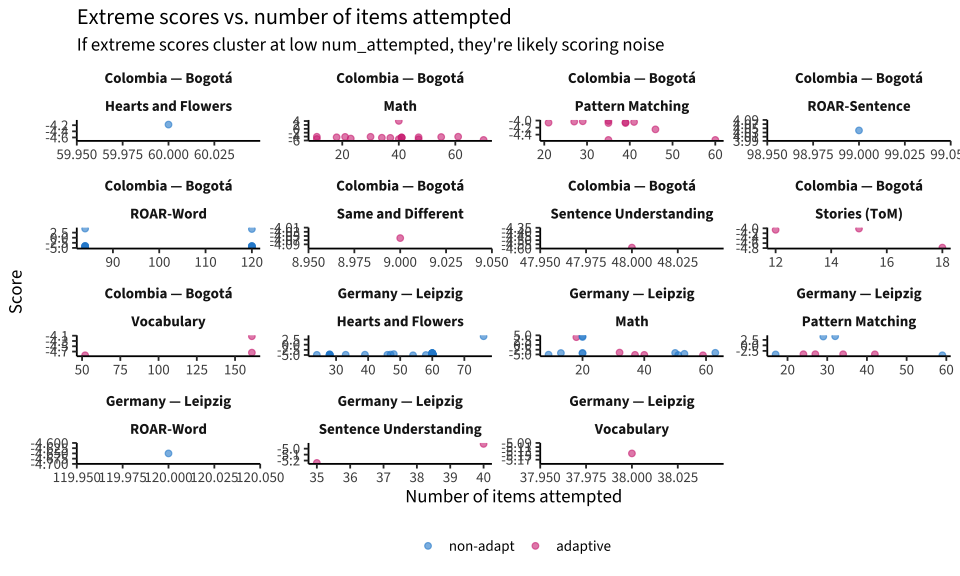
6. ROAR-Word super-low scores in Bogotá: zoom in
The ROAR-Word ability_cat distribution in Bogotá showed a clump of very low scores. Let’s look more closely.
rw_bog <- scores |>
  filter(dataset == "pilot_uniandes_co_bogota",
         task_id == "swr")

rw_bog |>
  ggplot(aes(x = age, y = score, color = adaptive)) +
  geom_point(alpha = 0.4) +
  geom_smooth(method = "loess", se = FALSE) +
  geom_hline(yintercept = -4, lty = 3, color = "red") +
  scale_color_manual(values = c(`FALSE` = "#268bd2", `TRUE` = "#d33682"),
                     na.value = "grey60", name = NULL) +
  labs(x = "Age", y = "ROAR-Word ability_cat θ",
       title = "ROAR-Word scores by age (Bogotá)",
       subtitle = "Red dotted = floor candidate (-4)")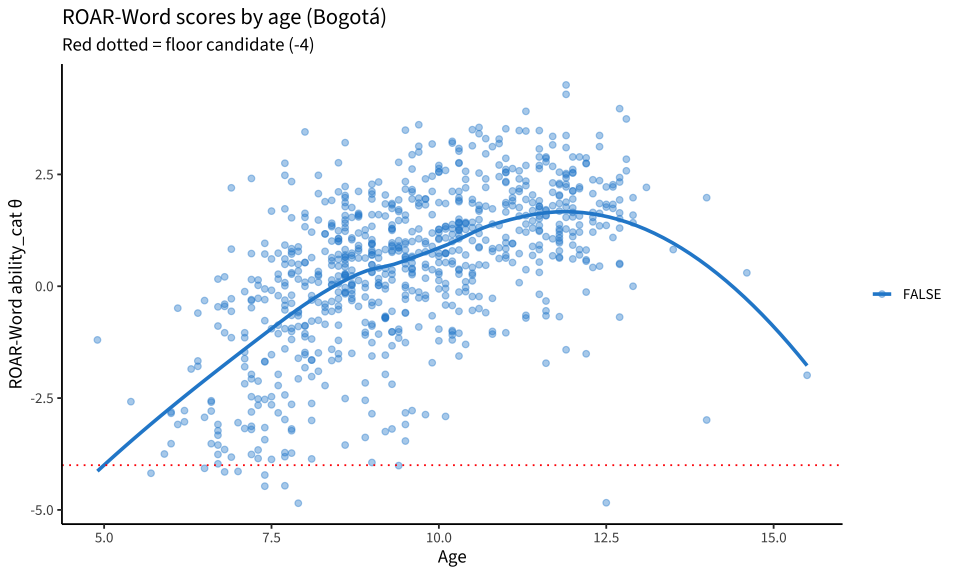
rw_bog |>
  filter(score < -3) |>
  arrange(score) |>
  select(user_id, age, run_id, score, score_se, num_attempted, adaptive,
         scoring_model, max_incorrect, max_time) |>
  head(15) |>
knitr::kable(digits = 2)| user_id | age | run_id | score | score_se | num_attempted | adaptive | scoring_model | max_incorrect | max_time |
|---|---|---|---|---|---|---|---|---|---|
| jgT7RubDVvUcPvVNsJONtULyrzO2 | 7.9 | k76DOVl5wWITCyw9SR5h | -4.85 | 0.64 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| JDROBrccAUBrdy41TLnA | 12.5 | CFw5lGVjZFi9IJtTkyzg | -4.84 | 0.65 | 84 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| ru4b1FfRep1mJKJs7z33 | 7.4 | 84BETlTJxPmkdvPGUaER | -4.47 | 0.74 | 84 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| O81U8Nab7LfyPtA56zMYN33IyQg2 | 7.7 | WKXIz4YN2ytirtVtIbn1 | -4.46 | 0.74 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| 75eh8hcvfFOcR75v8d6L6SO9H4l2 | 7.4 | 7b0EX4fZGtYpaCmZBB64 | -4.22 | 0.79 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| qNIMMnWbZoOotqpiCWuX | 5.7 | ucqZ9svdmhM0mhuchjvM | -4.18 | 0.79 | 84 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| 5H1OIWjTE6ZfoKweGAec | 6.8 | J6SReHz5TLNLmBTy2Q7A | -4.15 | 0.77 | 84 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| 8yxoCnh5GoOGc2rsOQ1VT80PGpi2 | 7.0 | iITAD15MJHpu6yVzb81d | -4.14 | 0.80 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| rr9pCAQKiIR9QHKeKrV7p99hqnF2 | 6.5 | 7pkDoPXsc366fjQJpPm7 | -4.07 | 0.80 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| IW8mg8kCLBkpmtqnTlnz | 9.4 | Jfv00K9FnPWsJfDc0Mx3 | -4.01 | 0.78 | 84 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| pXeB9QljD4QnsWIfvCpMd4gLirQ2 | 6.7 | vwrnZ4UJYdrWjSupaQ8w | -3.97 | 0.80 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| BrHbYub5haR6GdnG1N0JaUg6SQ73 | 9.0 | IUi2FbVmp4NnHGGVIsXe | -3.94 | 0.81 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| FGtePFe0BNUlEdDjmu5QfvwLZqf1 | 7.5 | 4nc9LgmkzeKtpscQ0NqR | -3.87 | 0.81 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| FTdiN4pZggd3fBi2oAYNXqW9dQn2 | 8.1 | adY641tnn60oagGqIU5K | -3.86 | 0.82 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
| V3EbvhhlzRWEBnFjVMynEZld1iE2 | 7.3 | Ko0pRbCM2ulFO8TShODk | -3.85 | 0.85 | 120 | FALSE | by_language_es-CO_rasch_f1 | NA | NA |
rw_bog |>
  ggplot(aes(x = num_attempted, fill = score < -3)) +
  geom_histogram(binwidth = 5, alpha = 0.7, position = "identity") +
  scale_fill_manual(values = c(`FALSE` = "steelblue", `TRUE` = "firebrick"),
                    labels = c("score ≥ -3", "score < -3"),
                    name = NULL) +
  labs(x = "Number of items attempted", y = "Runs",
       title = "ROAR-Word num_attempted, split by extreme-low score (Bogotá)")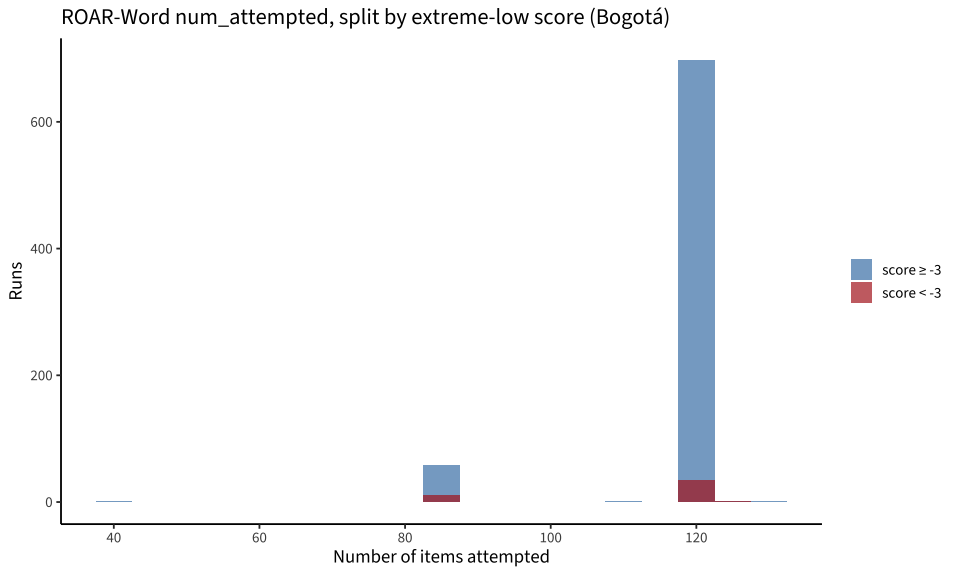
7. Score SE distribution — flag unreliable estimates
Per-run IRT SE: huge values mean the ability estimate is unreliable (insufficient information). Compare across (site, task).
waved |>
  ggplot(aes(x = score_se)) +
  geom_histogram(bins = 30, fill = "steelblue", color = "white") +
  facet_grid(dataset_label ~ task_category + task_label, scales = "free") +
  geom_vline(xintercept = 1, lty = 3, color = "red") +
  labs(x = "score_se", y = "Runs",
       title = "Score SE distribution (red = 1.0 threshold)") +
  theme(strip.text.x = element_text(angle = 0, size = 7),
        panel.spacing.x = unit(0.05, "lines"))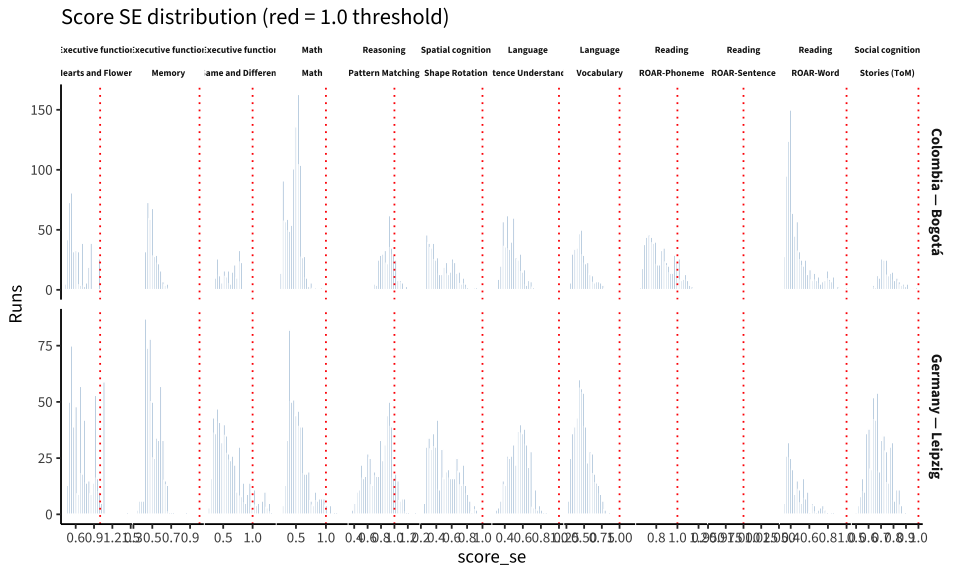
waved |>
  group_by(dataset_label, task_label) |>
  summarise(n = n(),
            n_se_gt_1 = sum(score_se > 1, na.rm = TRUE),
            pct_se_gt_1 = mean(score_se > 1, na.rm = TRUE) * 100,
            n_se_na = sum(is.na(score_se)),
            .groups = "drop") |>
  arrange(desc(pct_se_gt_1)) |>
knitr::kable(digits = 2)| dataset_label | task_label | n | n_se_gt_1 | pct_se_gt_1 | n_se_na |
|---|---|---|---|---|---|
| Colombia — Bogotá | Pattern Matching | 328 | 51 | 15.55 | 0 |
| Colombia — Bogotá | ROAR-Phoneme | 579 | 75 | 12.95 | 0 |
| Germany — Leipzig | Hearts and Flowers | 547 | 67 | 12.25 | 0 |
| Germany — Leipzig | Pattern Matching | 494 | 56 | 11.34 | 0 |
| Germany — Leipzig | Same and Different | 530 | 45 | 8.49 | 0 |
| Germany — Leipzig | Math | 513 | 7 | 1.36 | 0 |
| Colombia — Bogotá | Hearts and Flowers | 435 | 4 | 0.92 | 0 |
| Colombia — Bogotá | Vocabulary | 336 | 1 | 0.30 | 0 |
| Colombia — Bogotá | Shape Rotation | 412 | 1 | 0.24 | 0 |
| Colombia — Bogotá | Math | 909 | 1 | 0.11 | 0 |
| Colombia — Bogotá | Memory | 344 | 0 | 0.00 | 0 |
| Colombia — Bogotá | ROAR-Word | 806 | 0 | 0.00 | 0 |
| Colombia — Bogotá | Same and Different | 204 | 0 | 0.00 | 0 |
| Colombia — Bogotá | Sentence Understanding | 454 | 0 | 0.00 | 0 |
| Colombia — Bogotá | Stories (ToM) | 190 | 0 | 0.00 | 0 |
| Germany — Leipzig | Memory | 523 | 0 | 0.00 | 0 |
| Germany — Leipzig | ROAR-Word | 206 | 0 | 0.00 | 0 |
| Germany — Leipzig | Sentence Understanding | 424 | 0 | 0.00 | 0 |
| Germany — Leipzig | Shape Rotation | 463 | 0 | 0.00 | 0 |
| Germany — Leipzig | Stories (ToM) | 505 | 0 | 0.00 | 0 |
| Germany — Leipzig | Vocabulary | 499 | 0 | 0.00 | 0 |
| Colombia — Bogotá | ROAR-Sentence | 769 | 0 | NaN | 769 |
| Germany — Leipzig | ROAR-Sentence | 200 | 0 | NaN | 200 |
8. Pattern Matching & Sentence Understanding: T2 > T1 in both modes
Release notes call these out as systematically higher at T2 within both adaptive and non-adaptive. Plot T1 vs T2 mean by age band to see if it looks more like training or real development.
pairs |>
  filter(task_id %in% c("matrix-reasoning", "trog"),
         transition %in% c("NA→NA", "A→A")) |>
  ggplot(aes(x = score_t1, y = score_t2, color = transition)) +
  geom_abline(slope = 1, intercept = 0, lty = 3, color = "grey50") +
  geom_point(alpha = 0.4) +
  geom_smooth(method = "lm", se = TRUE) +
  facet_grid(dataset_label ~ task_label, scales = "free") +
  scale_color_brewer(palette = "Set2") +
  labs(x = "T1 score", y = "T2 score",
       title = "Pattern Matching & Sentence Understanding: T2 vs T1",
       color = NULL) +
  theme(legend.position = "bottom")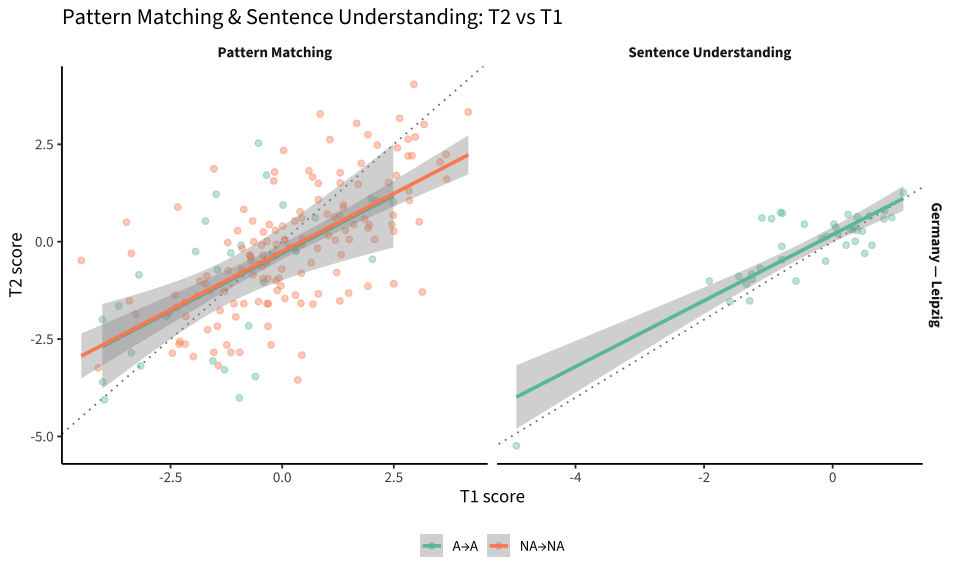
9. Memory (Bogotá): super-low scores
mem_bog <- scores |>
  filter(dataset == "pilot_uniandes_co_bogota", task_id == "memory-game")

mem_bog |>
  ggplot(aes(x = age, y = score)) +
  geom_point(alpha = 0.3) +
  geom_smooth(method = "loess", se = FALSE) +
  geom_hline(yintercept = -3, lty = 3, color = "red") +
  labs(x = "Age", y = "Memory IRT θ",
       title = "Memory scores by age (Bogotá)")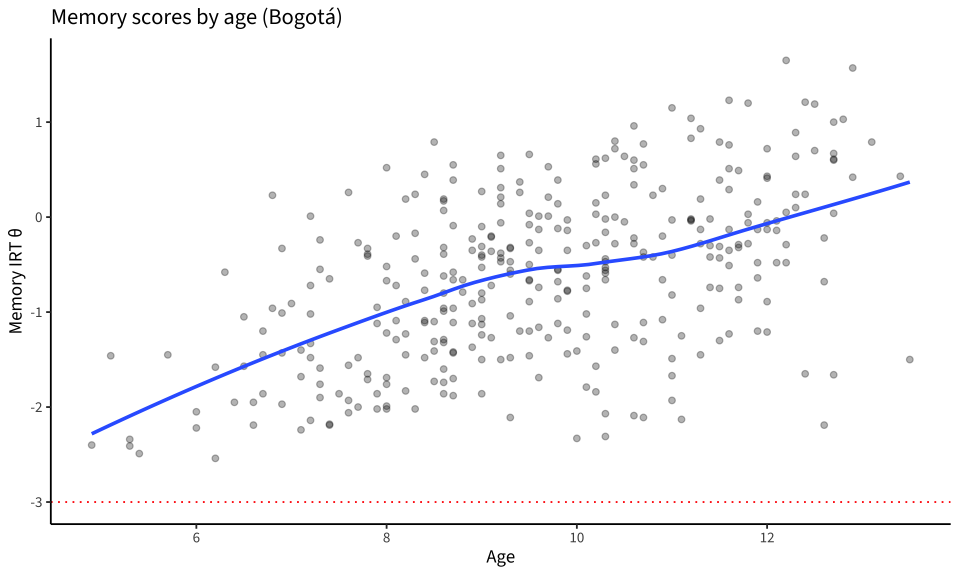
mem_bog |>
  filter(score < -3) |>
  arrange(score) |>
  select(user_id, age, run_id, score, score_se, num_attempted, adaptive,
         scoring_model) |>
  head(15) |>
knitr::kable(digits = 2)| user_id | age | run_id | score | score_se | num_attempted | adaptive | scoring_model |
|---|
10. Verdict table
Status codes:
- OK: usable as-is; growth signal trustworthy
- OK-mode: usable if you restrict to one administration mode (or split by it). NA→NA or A→A subsamples only.
- CAVEAT: usable but caveat-it heavily; effect size on growth is partly measurement artifact.
- DROP: known broken per release notes or local diagnostics — do not use for growth/SEM until next data release.
verdict <- tribble(
  ~dataset_label,            ~task_label,             ~status,    ~notes,
  # Leipzig
  "Germany — Leipzig",       "Hearts and Flowers",    "OK",       "Always non-adaptive at both waves; clean.",
  "Germany — Leipzig",       "Memory",                "OK",       "2026-08: DROP lifted. Grid is a calibrated item dimension, and the wave-1→2 grid switch shows continuous within-child θ (tasks/memory §4). Do not use raw sumscores across grids.",
  "Germany — Leipzig",       "Same and Different",    "OK",       "2026-08: corrected scoring landed (registry v2_3, DCC-confirmed final).",
  "Germany — Leipzig",       "Pattern Matching",      "OK",       "v1.2: bug fixed. Minor residual mode shift (+0.73); note T2>T1 training concern.",
  "Germany — Leipzig",       "Shape Rotation",        "OK",       "v1.2: bug fixed. Residual mode shift small.",
  "Germany — Leipzig",       "Math",                  "OK",       "v1.2: bug fixed; non-adapt−adapt shift now +0.30 (was +2.4). Mild EAP shrinkage across mode boundary.",
  "Germany — Leipzig",       "Vocabulary",            "OK",       "v1.2: bug fixed; shift now +0.10 (was +1.1). Clean.",
  "Germany — Leipzig",       "Sentence Understanding","OK",       "v1.2: bug fixed. Note T2>T1 training concern (release notes).",
  "Germany — Leipzig",       "Stories (ToM)",         "OK",       "No CAT at this site; modest signal.",
  "Germany — Leipzig",       "ROAR-Sentence",         "CAVEAT",   "Different score type (guessing-adjusted raw); thin T2.",
  "Germany — Leipzig",       "ROAR-Word",             "OK",       "ability_cat scale; engagement filter applied in cleaning.",

  # Bogotá
  "Colombia — Bogotá",       "Hearts and Flowers",    "OK",       "Always non-adaptive.",
  "Colombia — Bogotá",       "Memory",                "OK",       "2026-08: DROP lifted (see tasks/memory §4); super-low scores were the v1.0 bug. Sumscores not comparable across grids — use θ.",
  "Colombia — Bogotá",       "Same and Different",    "OK-mode",  "2026-08: corrected scoring landed (final). Still zero T2 at Bogotá — cross-sectional use only.",
  "Colombia — Bogotá",       "Pattern Matching",      "OK",       "v1.2: bug fixed. Residual mode shift −0.40.",
  "Colombia — Bogotá",       "Shape Rotation",        "OK",       "v1.2: bug fixed.",
  "Colombia — Bogotá",       "Math",                  "OK",       "v1.2: bug fixed; the apparent 'RTM' was the bug. Two-wave kids are NA→CAT, so mind mild EAP shrinkage.",
  "Colombia — Bogotá",       "Vocabulary",            "OK",       "v1.2: bug fixed. Thin T2 (n≈30).",
  "Colombia — Bogotá",       "Sentence Understanding","OK",       "Mostly mode-stable; positive growth.",
  "Colombia — Bogotá",       "Stories (ToM)",         "DROP",     "Zero T2 data (cross-sectional only).",
  "Colombia — Bogotá",       "ROAR-Sentence",         "OK",       "n≈165 with repeats; raw scale stable.",
  "Colombia — Bogotá",       "ROAR-Word",             "OK",       "Engagement filter applied (accuracy<.4 or median RT<500ms); floor cases are genuine non-readers.",
  "Colombia — Bogotá",       "ROAR-Phoneme",          "OK",       "Clean.",

  # Caquetá/Boyacá (rural Colombia) — wave 2 landed in the 2026-08 update.
  # Repeats concentrate in ROAR + Math; other tasks are cross-sectional so far.
  "Colombia — Caquetá/Boyacá", "Math",                 "OK",       "2026-08: 204 repeat pairs, cleanly CAT→CAT (mode-stable); mind EAP shrinkage.",
  "Colombia — Caquetá/Boyacá", "ROAR-Word",            "OK",       "2026-08: 201 repeat pairs, non-adaptive both waves; engagement filter applied.",
  "Colombia — Caquetá/Boyacá", "ROAR-Sentence",        "OK",       "2026-08: 174 repeat pairs; raw (guessing-adjusted) scale, non-IRT.",
  "Colombia — Caquetá/Boyacá", "ROAR-Phoneme",         "OK",       "2026-08: 210 repeat pairs, the largest ROAR-Phoneme longitudinal cell anywhere.",
  "Colombia — Caquetá/Boyacá", "Sentence Understanding","CAVEAT",  "Only 6 repeat pairs so far — cross-sectional for now.",
  "Colombia — Caquetá/Boyacá", "Vocabulary",           "CAVEAT",   "Only 4 repeat pairs so far — cross-sectional for now.",
  "Colombia — Caquetá/Boyacá", "Stories (ToM)",        "CAVEAT",   "Cross-sectional; also re-scored under registry v2_3 (see 00).",
  "Colombia — Caquetá/Boyacá", "Memory",               "CAVEAT",   "2026-08: scoring concern resolved (tasks/memory §4) but only 2 repeat pairs — cross-sectional for now.",
  "Colombia — Caquetá/Boyacá", "Same and Different",   "CAVEAT",   "2026-08: corrected scoring landed (final); cross-sectional so far.",
  "Colombia — Caquetá/Boyacá", "Hearts and Flowers",   "CAVEAT",   "4 repeat pairs; cross-sectional for now.",
  "Colombia — Caquetá/Boyacá", "Pattern Matching",     "CAVEAT",   "5 repeat pairs; cross-sectional for now.",
  "Colombia — Caquetá/Boyacá", "Shape Rotation",       "CAVEAT",   "1 repeat pair; cross-sectional for now."
)

verdict |>
  arrange(dataset_label, task_label) |>
knitr::kable()| dataset_label | task_label | status | notes |
|---|---|---|---|
| Colombia — Bogotá | Hearts and Flowers | OK | Always non-adaptive. |
| Colombia — Bogotá | Math | OK | v1.2: bug fixed; the apparent ‘RTM’ was the bug. Two-wave kids are NA→CAT, so mind mild EAP shrinkage. |
| Colombia — Bogotá | Memory | OK | 2026-08: DROP lifted (see tasks/memory §4); super-low scores were the v1.0 bug. Sumscores not comparable across grids — use θ. |
| Colombia — Bogotá | Pattern Matching | OK | v1.2: bug fixed. Residual mode shift −0.40. |
| Colombia — Bogotá | ROAR-Phoneme | OK | Clean. |
| Colombia — Bogotá | ROAR-Sentence | OK | n≈165 with repeats; raw scale stable. |
| Colombia — Bogotá | ROAR-Word | OK | Engagement filter applied (accuracy<.4 or median RT<500ms); floor cases are genuine non-readers. |
| Colombia — Bogotá | Same and Different | OK-mode | 2026-08: corrected scoring landed (final). Still zero T2 at Bogotá — cross-sectional use only. |
| Colombia — Bogotá | Sentence Understanding | OK | Mostly mode-stable; positive growth. |
| Colombia — Bogotá | Shape Rotation | OK | v1.2: bug fixed. |
| Colombia — Bogotá | Stories (ToM) | DROP | Zero T2 data (cross-sectional only). |
| Colombia — Bogotá | Vocabulary | OK | v1.2: bug fixed. Thin T2 (n≈30). |
| Colombia — Caquetá/Boyacá | Hearts and Flowers | CAVEAT | 4 repeat pairs; cross-sectional for now. |
| Colombia — Caquetá/Boyacá | Math | OK | 2026-08: 204 repeat pairs, cleanly CAT→CAT (mode-stable); mind EAP shrinkage. |
| Colombia — Caquetá/Boyacá | Memory | CAVEAT | 2026-08: scoring concern resolved (tasks/memory §4) but only 2 repeat pairs — cross-sectional for now. |
| Colombia — Caquetá/Boyacá | Pattern Matching | CAVEAT | 5 repeat pairs; cross-sectional for now. |
| Colombia — Caquetá/Boyacá | ROAR-Phoneme | OK | 2026-08: 210 repeat pairs, the largest ROAR-Phoneme longitudinal cell anywhere. |
| Colombia — Caquetá/Boyacá | ROAR-Sentence | OK | 2026-08: 174 repeat pairs; raw (guessing-adjusted) scale, non-IRT. |
| Colombia — Caquetá/Boyacá | ROAR-Word | OK | 2026-08: 201 repeat pairs, non-adaptive both waves; engagement filter applied. |
| Colombia — Caquetá/Boyacá | Same and Different | CAVEAT | 2026-08: corrected scoring landed (final); cross-sectional so far. |
| Colombia — Caquetá/Boyacá | Sentence Understanding | CAVEAT | Only 6 repeat pairs so far — cross-sectional for now. |
| Colombia — Caquetá/Boyacá | Shape Rotation | CAVEAT | 1 repeat pair; cross-sectional for now. |
| Colombia — Caquetá/Boyacá | Stories (ToM) | CAVEAT | Cross-sectional; also re-scored under registry v2_3 (see 00). |
| Colombia — Caquetá/Boyacá | Vocabulary | CAVEAT | Only 4 repeat pairs so far — cross-sectional for now. |
| Germany — Leipzig | Hearts and Flowers | OK | Always non-adaptive at both waves; clean. |
| Germany — Leipzig | Math | OK | v1.2: bug fixed; non-adapt−adapt shift now +0.30 (was +2.4). Mild EAP shrinkage across mode boundary. |
| Germany — Leipzig | Memory | OK | 2026-08: DROP lifted. Grid is a calibrated item dimension, and the wave-1→2 grid switch shows continuous within-child θ (tasks/memory §4). Do not use raw sumscores across grids. |
| Germany — Leipzig | Pattern Matching | OK | v1.2: bug fixed. Minor residual mode shift (+0.73); note T2>T1 training concern. |
| Germany — Leipzig | ROAR-Sentence | CAVEAT | Different score type (guessing-adjusted raw); thin T2. |
| Germany — Leipzig | ROAR-Word | OK | ability_cat scale; engagement filter applied in cleaning. |
| Germany — Leipzig | Same and Different | OK | 2026-08: corrected scoring landed (registry v2_3, DCC-confirmed final). |
| Germany — Leipzig | Sentence Understanding | OK | v1.2: bug fixed. Note T2>T1 training concern (release notes). |
| Germany — Leipzig | Shape Rotation | OK | v1.2: bug fixed. Residual mode shift small. |
| Germany — Leipzig | Stories (ToM) | OK | No CAT at this site; modest signal. |
| Germany — Leipzig | Vocabulary | OK | v1.2: bug fixed; shift now +0.10 (was +1.1). Clean. |
11. Recommended filter helpers
These functions encode the verdict above. They are exported to be used by 02 and 03. Anything not flagged is left alone.
#' Drop runs from tasks marked DROP and (optionally) restrict mode-sensitive
#' tasks to within-mode pairs.
clean_for_growth <- function(scores, mode_strict = TRUE) {
  drops <- tribble(
    ~dataset,                       ~task_id,
    "pilot_mpieva_de_main",         "memory-game",
    "pilot_uniandes_co_bogota",     "memory-game",
    "pilot_uniandes_co_bogota",     "same-different-selection",
    "pilot_uniandes_co_bogota",     "theory-of-mind"
  )
  out <- scores |> anti_join(drops, by = c("dataset", "task_id"))
  if (mode_strict) {
    # Within each (dataset, child, task) keep only runs whose mode matches
    # that child's first run on that task (so we never mix modes within a
    # child's longitudinal trajectory).
    out <- out |>
      group_by(dataset, user_id, task_id) |>
      arrange(age) |>
      filter(is.na(adaptive) | adaptive == first(na.omit(adaptive))) |>
      ungroup()
  }
  out
}

#' Drop runs that look like truncated administrations (very few items
#' attempted) where this is most likely to confound the IRT score.
drop_short_runs <- function(scores, min_attempted = 5) {
  scores |>
    filter(is.na(num_attempted) | num_attempted >= min_attempted)
}

write_rds(verdict, here("data", "task_site_verdict.rds"))
Summary (v1.2, updated for the 2026-08 per-site snapshot)
2026-08 update. The audit now runs on the per-site processed datasets (see 00). What’s new for integrity purposes: (a) rural Colombia’s second wave — repeats concentrate in ROAR (pa/swr/sre) + Math, with Math cleanly CAT→CAT (no mode transition to worry about), while the other core tasks remain cross-sectional there; (b) the new sites (Sheffield, MPIB-YS, UTDT-YS, Boston) are single-wave, so no growth verdicts yet — their rows will be added when repeats land; (c) scores were re-scored under registry v2_3 — ToM changed most (r = 0.88 vs June scores), so ToM-specific conclusions should be re-validated; (d) unscoreable runs now arrive as explicit exclusion rows (dropped in 00’s cleaning) rather than being silently absent.
With the column-order scoring bug fixed upstream, most tasks are now OK — the large mode-confound caveats from the v1.0 audit were the bug, not the data. Three genuinely-remaining issues survive:
- Memory (
memory-game) — DROP lifted (2026-08). Grid is a calibrated item dimension, and the Leipzig wave-1→2 grid switch shows continuous within-child θ while raw sumscores visibly break (tasks/memory §4). Use θ, never cross-grid sumscores. The old super-low Bogotá scores were the v1.0 bug. - Same & Different — resolved (2026-08). Corrected scoring landed in registry v2_3 (DCC-confirmed final). Still zero T2 at Bogotá → cross-sectional there.
- ROAR-Word non-engagement — handled in cleaning. A subset of runs floor at θ = −6: ~17 are rushers (median RT < 500 ms), the rest genuine near-chance non-readers.
00applies the filter (accuracy < 0.4 OR median RT < 500 ms). Floor rates: rural Colombia 16% > Western 7.3% > Bogotá 5.5% > Leipzig 1.6%.
Plus two lower-grade caveats: the unflagged adaptive rows (235, backfilled to non-adaptive in cleaning — confirmed with DCC) and a small EAP-shrinkage difference for the few tasks whose two-wave data crosses a CAT/non-CAT boundary (notably Bogotá math). Training-vs-development for Pattern Matching & Sentence Understanding (T2 > T1, release notes) remains an open question, not a defect.
The verdict table is saved to data/task_site_verdict.rds. Cleaning helpers (backfill_adaptive_na, roar_word_engagement_drops, clean_levante_scores) now live in common.R and are applied in 00_load_data.