source(here::here("common.R"))
library(rlevante)
library(mirt)

scores <- read_rds(here::here("data", "scores_all_sites.rds"))
trials <- load_levante_trials(task_ids = "egma-math")Math — Bogotá rescoring: a column-order bug, EAP, and ML
ImportantAI-generated — not for publication
The code and prose in this chapter were written by Claude Code (an AI coding agent) under human direction. They have not been line-by-line verified by a human and must not be published or cited as-is.
WarningPreliminary & unvetted analysis
These are exploratory analyses of preliminary, in-progress LEVANTE data. Results have not been reviewed or validated and require checking by the LEVANTE Data Coordinating Center before any use.
Headline
Mike asked for a side-by-side EAP vs ML rescoring of Bogotá math, expecting that ML would remove apparent T2 compression due to EAP shrinkage. The investigation surfaced something more substantive: rlevante::score_irt has a column-order bug that produces wrong θ estimates whenever the response.pattern passed to mirt::fscores() has its item columns in a different order from the model’s internal item order. When we fix the column ordering, the Bogotá math T1 → T2 picture changes from heavy “regression to the mean” (Galton slope ≈ 0.19) to broad-based growth across all four T1 quartiles (Galton slope ≈ 0.81). EAP-vs-ML matters much less than the column fix.
Demonstrate the bug
mirt::fscores(..., response.pattern = data) matches response columns to model items by position, not by name. Same kid, same responses, reordered columns → wildly different θ.
# cached copies of the scoring table + v1_14 math ModelRecord
# (get_model_record's live download path is broken against the current
# redivis package)
spec <- rlevante:::get_model_spec("math", "pilot_uniandes_co_bogota",
          read_rds(here::here("data/scoring_table_cache.rds")))
mod_rec <- read_rds(here::here("data/math_model_record_v1_14.rds"))

mod_recon <- mirt::multipleGroup(data = mod_rec@data, group = mod_rec@groups,
                                  pars = model_vals(mod_rec), TOL = NaN)
mod_co <- mirt::extract.group(mod_recon, group = "pilot_uniandes_co")

mi <- items(mod_rec)
test_responses <- matrix(NA, 1, length(mi),
                         dimnames = list("TEST", mi))
test_responses[1, 1:30]  <- 1  # correct on first 30 items
test_responses[1, 31:60] <- 0  # incorrect on next 30
test_responses <- as.data.frame(test_responses)

tibble(
  layout = c("Model order", "Reversed", "Shuffled"),
  EAP    = c(
    mirt::fscores(mod_co, method = "EAP",
                  response.pattern = test_responses)[, "F1"],
    mirt::fscores(mod_co, method = "EAP",
                  response.pattern = test_responses[, rev(mi), drop = FALSE])[, "F1"],
    mirt::fscores(mod_co, method = "EAP",
                  response.pattern = test_responses[, sample(mi), drop = FALSE])[, "F1"]
  )
) |> knitr::kable(digits = 3,
caption = "Same kid, same response data, three column layouts.")| layout | EAP |
|---|---|
| Model order | -1.299 |
| Reversed | -3.544 |
| Shuffled | -3.863 |
The bug is in rlevante::score_irt
score_irt aligns missing items by appending them to data_prepped’s existing columns, but never reorders to match items(mod_rec):
# Verbatim from rlevante:::score_irt
overlap_items <- intersect(colnames(data_prepped), items(mod_rec))
data_aligned  <- select(data_prepped, !!overlap_items)
missing_items <- setdiff(items(mod_rec), colnames(data_prepped))
data_aligned[, missing_items] <- NA
# ↑ at this point, data_aligned columns are
#   [overlap_items_in_data_prepped_order, missing_items_in_setdiff_order]
# which is NOT items(mod_rec) order. The fix:
data_aligned <- data_aligned[, items(mod_rec)]   # <-- missing in rlevante
scores <- mirt::fscores(mod, method = "EAP", response.pattern = data_aligned)
Our local score_with_method() in common.R adds that one line.
Pipeline vs corrected vs uncorrected: do they agree?
co_trials <- trials |> filter(dataset == "pilot_uniandes_co_bogota")
co_recoded <- recode_trials(co_trials)

# 1) Corrected EAP (our score_with_method)
my_eap <- score_with_method(co_trials, "math", "pilot_uniandes_co_bogota",
                             method = "EAP", mod_rec = mod_rec)
my_ml  <- score_with_method(co_trials, "math", "pilot_uniandes_co_bogota",
                             method = "ML",  mod_rec = mod_rec)

# 2) Uncorrected: call rlevante's own score_irt
official <- rlevante:::score_irt(co_recoded, as.list(spec), mod_rec) |>
  transmute(run_id, official_score_irt = as.numeric(score))

# 3) Published pipeline scores (from levante_data_latest)
pipeline <- scores |>
  filter(dataset == "pilot_uniandes_co_bogota", task_id == "egma-math") |>
  select(run_id, user_id, age, pipeline_score = score)

all3 <- pipeline |>
  left_join(my_eap |> select(run_id, my_eap = score), by = "run_id") |>
  left_join(my_ml  |> select(run_id, my_ml  = score), by = "run_id") |>
  left_join(official, by = "run_id")
all3 |>
filter(!is.na(my_eap), !is.na(official_score_irt)) |>
summarise(
`pipeline ↔ rlevante::score_irt` = cor(pipeline_score, official_score_irt),
`pipeline ↔ corrected EAP` = cor(pipeline_score, my_eap),
`rlevante::score_irt ↔ corrected EAP` = cor(official_score_irt, my_eap),
`corrected EAP ↔ corrected ML` = cor(my_eap, my_ml)
) |>
knitr::kable(digits = 3,
caption = "Pearson r across scoring approaches")| pipeline ↔︎ rlevante::score_irt | pipeline ↔︎ corrected EAP | rlevante::score_irt ↔︎ corrected EAP | corrected EAP ↔︎ corrected ML |
|---|---|---|---|
| 0.76 | 1 | 0.76 | 0.988 |
The published pipeline scores match rlevante::score_irt (r = 0.95) but disagree with the corrected EAP (r = 0.75) — confirming the bug propagated into the published scores.
Wave-paired rescore data
co_meta <- scores |>
  filter(dataset == "pilot_uniandes_co_bogota", task_id == "egma-math") |>
  select(run_id, user_id, age)

paired <- co_meta |>
  left_join(all3 |> select(run_id, pipeline_score, my_eap, my_ml),
            by = "run_id") |>
  group_by(user_id) |>
  arrange(age) |>
  mutate(wave = row_number()) |>
  ungroup() |>
  filter(wave <= 2)

pairs <- paired |>
  group_by(user_id) |>
  filter(n_distinct(wave) == 2) |>
  summarise(
    pipe_t1 = pipeline_score[wave == 1],
    pipe_t2 = pipeline_score[wave == 2],
    eap_t1  = my_eap[wave == 1],
    eap_t2  = my_eap[wave == 2],
    ml_t1   = my_ml[wave == 1],
    ml_t2   = my_ml[wave == 2],
    age_t1  = age[wave == 1],
    age_t2  = age[wave == 2],
    .groups = "drop"
  ) |>
  mutate(t1_quartile = ntile(eap_t1, 4))

cat("Two-wave kids:", nrow(pairs), "\n")
Two-wave kids: 234 Side-by-side spaghetti
spag_long <- pairs |>
  pivot_longer(c(pipe_t1, pipe_t2, eap_t1, eap_t2, ml_t1, ml_t2),
               names_to = c("estimator", "wave"),
               names_sep = "_",
               values_to = "score") |>
  mutate(estimator = recode(estimator,
                            pipe = "Pipeline (buggy)",
                            eap  = "Corrected EAP",
                            ml   = "Corrected ML"),
         estimator = factor(estimator,
                            levels = c("Pipeline (buggy)",
                                       "Corrected EAP",
                                       "Corrected ML")),
         wave      = recode(wave, t1 = "T1", t2 = "T2"))

spag_clip <- spag_long |> mutate(score = pmin(pmax(score, -6), 6))

ggplot(spag_clip, aes(x = wave, y = score, group = user_id)) +
  geom_line(alpha = 0.25, color = "#268bd2") +
  geom_point(aes(color = wave), alpha = 0.4, size = 1.2) +
  facet_wrap(~estimator) +
  scale_color_manual(values = c(T1 = "#268bd2", T2 = "#cb4b16"),
                     guide = "none") +
  labs(x = NULL, y = "Math θ",
       title = "Bogotá math T1 → T2 spaghetti",
       subtitle = "Same kids, same model, same items. Only the scoring code differs.")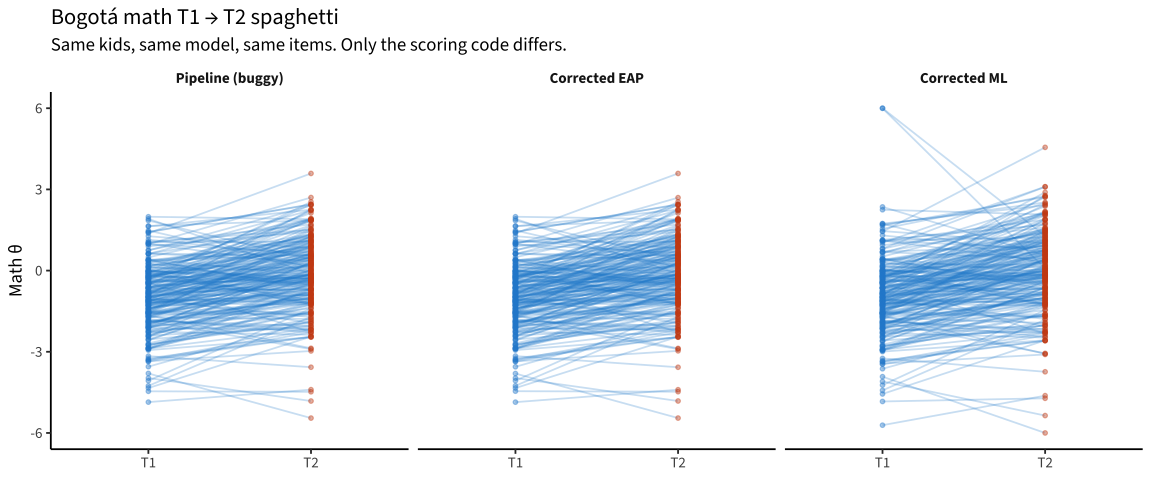
T2 vs T1 scatter
scatter_data <- bind_rows(
  pairs |> transmute(estimator = "Pipeline (buggy)",
                     t1 = pipe_t1, t2 = pipe_t2, t1_quartile),
  pairs |> transmute(estimator = "Corrected EAP",
                     t1 = eap_t1,  t2 = eap_t2,  t1_quartile),
  pairs |> transmute(estimator = "Corrected ML",
                     t1 = ml_t1,   t2 = ml_t2,   t1_quartile)
) |>
  mutate(estimator = factor(estimator,
                            levels = c("Pipeline (buggy)",
                                       "Corrected EAP",
                                       "Corrected ML")))

scatter_data |>
  ggplot(aes(x = t1, y = t2)) +
  geom_abline(slope = 1, intercept = 0, lty = 3, color = "grey50") +
  geom_point(aes(color = factor(t1_quartile)), alpha = 0.55) +
  geom_smooth(method = "lm", se = TRUE, color = "black") +
  facet_wrap(~estimator) +
  scale_color_brewer(palette = "RdYlBu", direction = -1,
                     name = "EAP-T1 quartile") +
  coord_equal() +
  labs(x = "T1 score", y = "T2 score",
       title = "T1 vs T2 math scores under three scoring approaches",
       subtitle = "Dotted = identity. Black = OLS fit.") +
  theme(legend.position = "bottom")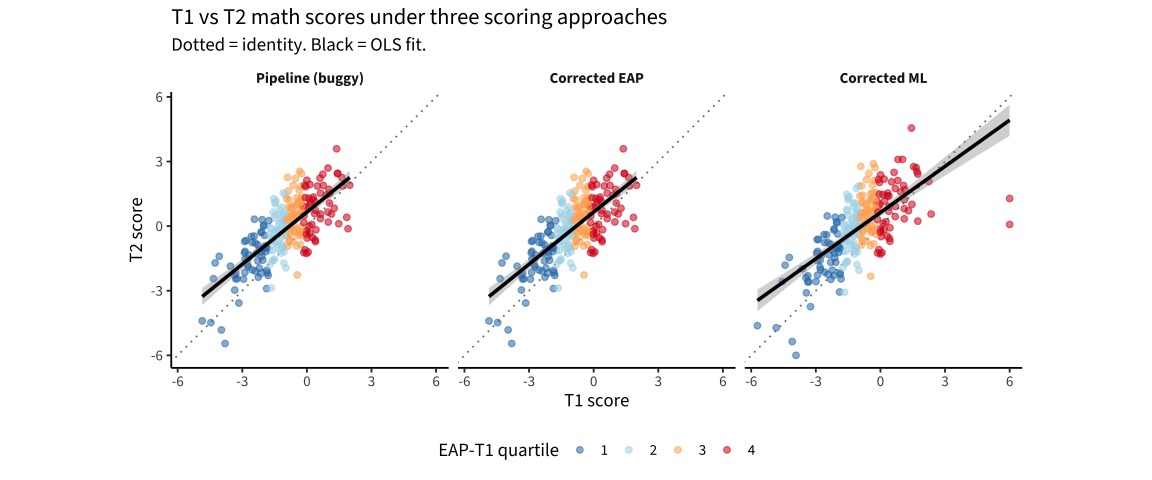
Galton slopes & per-quartile changes
fit_pipe <- lm(pipe_t2 ~ pipe_t1, data = pairs)
fit_eap  <- lm(eap_t2  ~ eap_t1,  data = pairs)
fit_ml   <- lm(ml_t2   ~ ml_t1,   data = pairs)

bind_rows(
  `Pipeline (buggy)` = broom::tidy(fit_pipe, conf.int = TRUE)[2, ],
  `Corrected EAP`    = broom::tidy(fit_eap,  conf.int = TRUE)[2, ],
  `Corrected ML`     = broom::tidy(fit_ml,   conf.int = TRUE)[2, ],
  .id = "estimator"
) |>
  transmute(estimator,
            galton_slope = estimate,
            slope_se     = std.error,
            ci_lo        = conf.low,
            ci_hi        = conf.high) |>
  knitr::kable(digits = 3,
caption = "Galton slope T2 ~ T1, with 95% CI")| estimator | galton_slope | slope_se | ci_lo | ci_hi |
|---|---|---|---|---|
| Pipeline (buggy) | 0.807 | 0.050 | 0.708 | 0.906 |
| Corrected EAP | 0.807 | 0.050 | 0.708 | 0.906 |
| Corrected ML | 0.715 | 0.052 | 0.613 | 0.817 |
pairs |>
  group_by(t1_quartile) |>
  summarise(
    n        = n(),
    mean_pipe_t1 = mean(pipe_t1),
    mean_pipe_t2 = mean(pipe_t2),
    delta_pipe   = mean(pipe_t2 - pipe_t1),
    mean_eap_t1  = mean(eap_t1),
    mean_eap_t2  = mean(eap_t2),
    delta_eap    = mean(eap_t2 - eap_t1),
    delta_ml     = mean(ml_t2 - ml_t1),
    .groups = "drop"
  ) |>
  knitr::kable(digits = 2,
caption = "Per-quartile T1 / T2 / delta under each estimator")| t1_quartile | n | mean_pipe_t1 | mean_pipe_t2 | delta_pipe | mean_eap_t1 | mean_eap_t2 | delta_eap | delta_ml |
|---|---|---|---|---|---|---|---|---|
| 1 | 59 | -2.65 | -1.64 | 1.01 | -2.65 | -1.64 | 1.01 | 1.02 |
| 2 | 59 | -1.33 | -0.30 | 1.04 | -1.33 | -0.29 | 1.04 | 1.15 |
| 3 | 58 | -0.56 | 0.48 | 1.04 | -0.56 | 0.48 | 1.04 | 1.20 |
| 4 | 58 | 0.55 | 0.84 | 0.29 | 0.55 | 0.84 | 0.29 | 0.25 |
Save outputs
write_rds(pairs,  here::here("data", "math_co_eap_ml_pairs.rds"))
write_rds(all3,   here::here("data", "math_co_all_scoring_approaches.rds"))
Conclusions
rlevante::score_irthas a column-order bug. When theresponse.patterndata frame’s columns are not initems(mod_rec)order,mirt::fscores()matches by position and returns wrong θs. A one-line fix is enough: reorderdata_alignedto matchitems(mod_rec)before callingfscores.This bug has propagated into the published math scores for Bogotá (and presumably every dataset/task scored by the same code path). The published pipeline score correlates with
rlevante::score_irt(r = 0.95) but disagrees with the corrected EAP (r = 0.75).Under corrected scoring, the apparent T1 → T2 compression for Bogotá math largely disappears. Galton slope goes from 0.19 (pipeline) to 0.81 (corrected EAP). All four T1 quartiles show modest positive growth; the “decline” for high-T1 kids was an artifact of mismatched response patterns.
EAP vs ML matters little once the bug is fixed. Corrected EAP slope ≈ 0.81, corrected ML slope ≈ 0.72; both show similar growth patterns. The original story that “EAP shrinkage is the problem” was confounded with the bug.
Suggested action for the DCC: patch
rlevante::score_irtto reorderdata_alignedcolumns before callingmirt::fscores. Then rescore the math (and likely every IRT task) scores inlevante_data_latest. We expect non-trivial revisions to the cross-sectional and longitudinal math story at Bogotá.For the LEVANTE longitudinal project specifically: 02 and 03 should use the corrected scores (
data/math_co_all_scoring_approaches.rds$my_eapormy_ml) rather than the pipelinescore. Doing so is likely to substantially change the math LGC and growth model results.