Code
source(here::here("common.R"))
sc <- read_rds(here("data/scores_all_sites.rds"))
tr <- load_levante_trials(task_ids = c("sre","pa")) |> mutate(correct = as.numeric(correct))The code and prose in this chapter were written by Claude Code (an AI coding agent) under human direction. They have not been line-by-line verified by a human and must not be published or cited as-is.
These are exploratory analyses of preliminary, in-progress LEVANTE data. Results have not been reviewed or validated and require checking by the LEVANTE Data Coordinating Center before any use.
The two remaining ROAR literacy measures, which use different scoring from the core tasks:
pa) — phonological awareness, scored with a by-language Rasch IRT model (separate es-CO and en-US calibrations; no German). Items: pa_{subtype}_{word} with subtypes fsm (first-sound matching), lsm (last-sound matching), del (deletion).sre) — sentence reading efficiency, a speeded task scored as a guessing-adjusted, z-scored correct-count ((correct − incorrect) / 180, standardized) — not an IRT θ, so it is not on the same scale as the other tasks and individual item difficulties aren’t calibrated.source(here::here("common.R"))
sc <- read_rds(here("data/scores_all_sites.rds"))
tr <- load_levante_trials(task_ids = c("sre","pa")) |> mutate(correct = as.numeric(correct))pa_ip <- load_item_parameters() |> filter(task_id == "pa") |>
mutate(subtype = str_extract(item_uid, "(?<=pa_)[a-z]+"),
subtype = recode(subtype, fsm = "first-sound", lsm = "last-sound",
del = "deletion"))
pa_ip |> group_by(subset, subtype) |>
summarise(n_items = n(), mean_difficulty = mean(difficulty),
.groups = "drop") |>
pivot_wider(names_from = subset, values_from = c(n_items, mean_difficulty)) |>
knitr::kable(digits = 2, caption = "PA mean item difficulty by subtype × language")| subtype | n_items_en-US | n_items_es-CO | mean_difficulty_en-US | mean_difficulty_es-CO |
|---|---|---|---|---|
| deletion | 19 | NA | -1.91 | NA |
| first-sound | 19 | 29 | -2.46 | -1.11 |
| last-sound | 19 | 24 | -1.42 | -0.46 |
pa_ip |>
  ggplot(aes(x = subtype, y = difficulty, color = subset)) +
  geom_hline(yintercept = 0, lty = 3, color = "grey70") +
  geom_jitter(width = 0.15, alpha = 0.6) +
  stat_summary(fun = mean, geom = "crossbar", width = 0.4, linewidth = 0.4) +
  scale_color_brewer(palette = "Set1", name = "Language") +
  labs(x = NULL, y = "Item difficulty (logits)",
       title = "PA item difficulty by phoneme-manipulation subtype")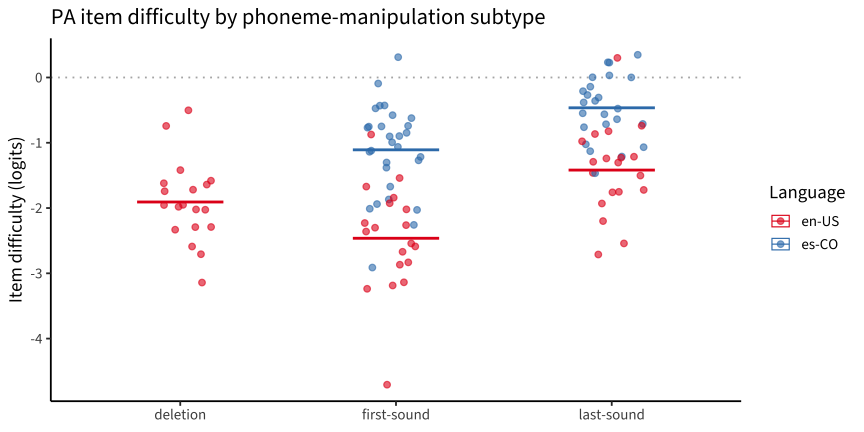
First-sound matching is easiest, last-sound matching harder — the expected ordering for phonological-awareness manipulations. (Deletion items appear in the trial data but are sparsely calibrated.)
sc |> filter(task_id == "pa", !is.na(score), !is.na(age)) |>
  ggplot(aes(x = age, y = score, color = dataset_label)) +
  geom_point(alpha = 0.25, size = 0.7) +
  geom_smooth(method = "lm", se = TRUE) +
  scale_color_brewer(palette = "Set1", name = NULL) +
  labs(x = "Age (years)", y = "PA ability (θ)",
       title = "ROAR-Phoneme rises with age") +
  theme(legend.position = "bottom")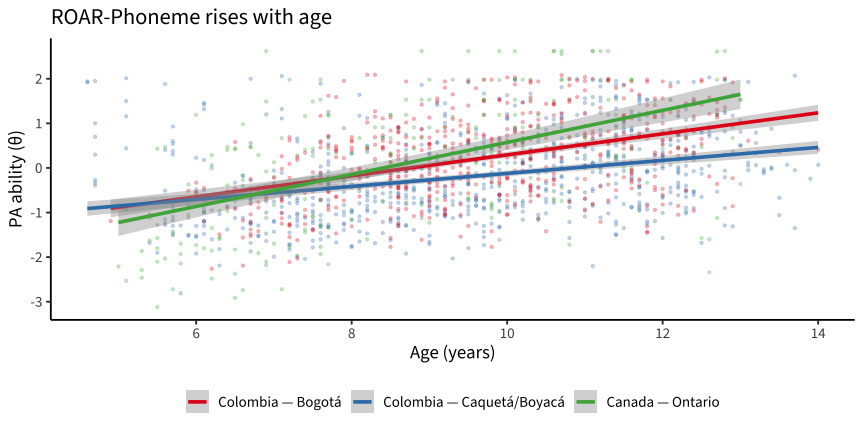
sc |> filter(task_id == "pa", !is.na(score), !is.na(age)) |>
  group_by(dataset_label) |> filter(n() >= 30) |>
  summarise(n = n(), cor_age = cor(score, age), .groups = "drop") |>
knitr::kable(digits = 2, caption = "PA age correlation by site (no German PA)")| dataset_label | n | cor_age |
|---|---|---|
| Colombia — Bogotá | 578 | 0.44 |
| Colombia — Caquetá/Boyacá | 725 | 0.34 |
| Canada — Ontario | 251 | 0.54 |
A speeded efficiency measure: the score is a standardized guessing-adjusted count, so its scale is task-internal (mean ≈ 0). All four data-rich sites have it.
sc |> filter(task_id == "sre", !is.na(score)) |>
  ggplot(aes(x = score, fill = dataset_label)) +
  geom_density(alpha = 0.4) +
  scale_fill_brewer(palette = "Set1", name = NULL) +
  labs(x = "SRE score (guessing-adjusted, z-scaled)", y = "Density",
       title = "SRE score distribution by site") +
  theme(legend.position = "bottom")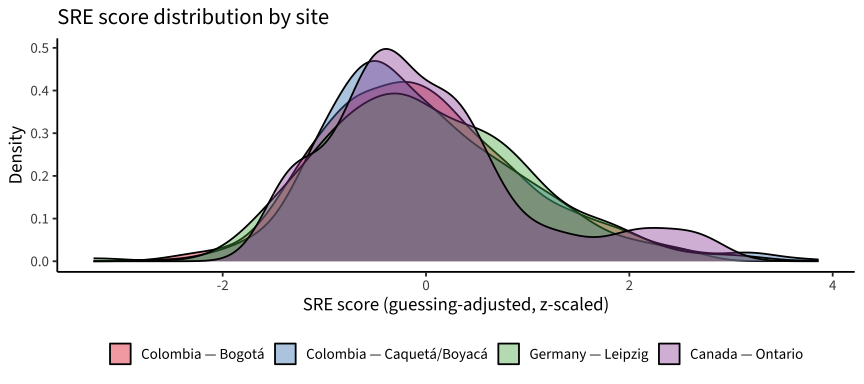
sc |> filter(task_id == "sre", !is.na(score), !is.na(age)) |>
  ggplot(aes(x = age, y = score, color = dataset_label)) +
  geom_point(alpha = 0.25, size = 0.7) +
  geom_smooth(method = "lm", se = TRUE) +
  scale_color_brewer(palette = "Set1", name = NULL) +
  labs(x = "Age (years)", y = "SRE score",
       title = "ROAR-Sentence rises with age") +
  theme(legend.position = "bottom")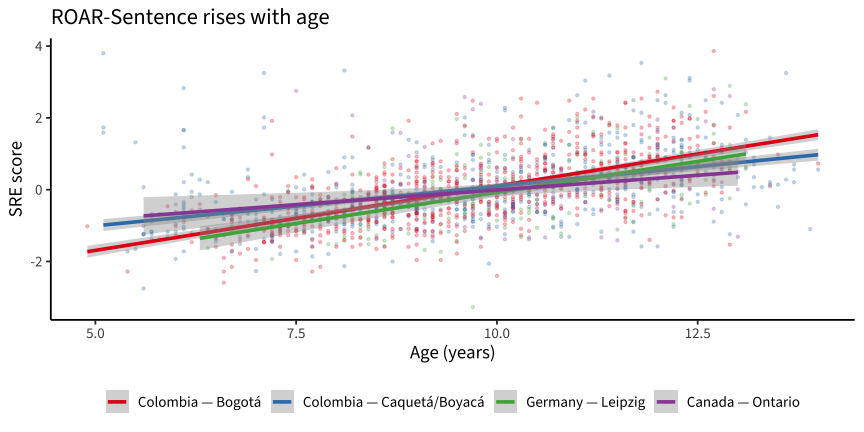
# the speeded nature: how many sentences reached, and accuracy among reached
tr |> filter(task_id == "sre") |>
  group_by(dataset_label, run_id) |>
  summarise(n_reached = n(), acc = mean(correct, na.rm = TRUE), .groups = "drop") |>
  group_by(dataset_label) |>
  summarise(median_sentences_reached = median(n_reached),
            median_accuracy = round(median(acc), 2), .groups = "drop") |>
knitr::kable(caption = "SRE is speeded: sentences reached varies; accuracy among reached is high")| dataset_label | median_sentences_reached | median_accuracy |
|---|---|---|
| Colombia — Bogotá | 34 | 0.89 |
| Colombia — Caquetá/Boyacá | 29 | 0.82 |
| Germany — Leipzig | 43 | 0.93 |
| Canada — Ontario | 61 | 0.94 |
sc |> filter(task_id == "sre", !is.na(score), !is.na(age)) |>
  group_by(dataset_label) |> filter(n() >= 30) |>
  summarise(n = n(), cor_age = cor(score, age), .groups = "drop") |>
knitr::kable(digits = 2, caption = "SRE age correlation by site")| dataset_label | n | cor_age |
|---|---|---|
| Colombia — Bogotá | 720 | 0.63 |
| Colombia — Caquetá/Boyacá | 608 | 0.46 |
| Germany — Leipzig | 183 | 0.54 |
| Canada — Ontario | 111 | 0.27 |